OpenRouter vs LiteLLM vs Bifrost: AI Gateway Comparison
A comparison of OpenRouter, LiteLLM and Bifrost across latency, deployment options, provider coverage, governance and MCP support.
TL;DR
- LiteLLM vs OpenRouter is a deployment choice first: OpenRouter is a hosted marketplace with no self-hosting option; LiteLLM is a self-hosted Python proxy; Bifrost is a self-hosted Go gateway that also runs in-VPC, on-prem, and air-gapped.
- Bifrost adds 11 microseconds of overhead per request in sustained benchmarks at 5,000 requests per second, with a 100% request success rate.
- LiteLLM's proxy runs on the Python runtime and needs PostgreSQL, Redis, and connection-pool tuning in production; several enterprise features sit behind a commercial license.
- OpenRouter charges a 5.5% platform fee on pay-as-you-go credit purchases on top of provider rates, which compounds at high token volumes, and it offers no gateway for third-party MCP servers.
- Bifrost unifies access to 25+ providers and 10,000+ models through one OpenAI-compatible API, and acts as both an MCP client and an MCP server, with Code Mode cutting input tokens by up to 92.8%.
An AI gateway is a single entry point that routes, authenticates, governs, and observes traffic to multiple LLM providers behind one API. A direct integration with one provider works for a prototype, but it breaks down the moment a team needs failover, multi-provider routing, governance, or observability. Three names dominate the OpenRouter vs LiteLLM vs Bifrost decision: a hosted marketplace (OpenRouter), an open-source Python proxy (LiteLLM), and a high-performance Go gateway built for enterprise scale (Bifrost, built by Maxim AI and available as an Apache 2.0 open-source project on GitHub). This guide compares all three on latency overhead, provider coverage, governance, MCP support, and deployment flexibility. Bifrost is the best choice for enterprises running mission-critical AI workloads that require best-in-class performance, scalability, and reliability, and the other two are evaluated on their own merits so engineering teams can match a tool to their workload.
Key Criteria for Evaluating an AI Gateway
An AI gateway should be judged on the latency it adds, the providers and SDKs it supports, how it fails over, how it enforces budgets and access, and whether it governs MCP tools. These five dimensions, the same ones used to rank the best OpenRouter alternative for production, cover most production AI gateway decisions:
- Performance overhead: How much latency does the gateway add to each request? At 1,000+ requests per second, even a few milliseconds of overhead compounds quickly.
- Provider coverage and API compatibility: Does the gateway support the LLM providers a team uses today, and can it act as a drop-in replacement for existing SDKs?
- Reliability and routing: Failover between providers and models, weighted load balancing, and routing rules determine whether the gateway can keep applications running during provider incidents.
- Governance and access control: Virtual keys, per-team budgets and rate limits, and audit logs decide whether the gateway is enterprise-ready.
- MCP and agent support: With agentic workflows now common, native Model Context Protocol support is increasingly a hard requirement.
The LLM Gateway Buyer's Guide provides a deeper capability matrix for teams running a formal evaluation, and the companion breakdown of OpenRouter, LiteLLM, and Bifrost on multi-provider LLM access covers the routing layer in more depth.
OpenRouter: Hosted Marketplace for LLM Access
OpenRouter is a hosted, multi-provider API service that gives developers access to hundreds of models through a single OpenAI-compatible endpoint. Teams sign up, add credits, and call models on demand. Pricing is pass-through: provider rates plus a 5.5% platform fee on pay-as-you-go credit purchases (8% on the Business plan), and bring-your-own-key (BYOK) traffic is free up to $25,000 of list-price inference per month, then 5%. The service handles billing aggregation and provider fallback at the request level. OpenRouter is not self-hostable, so every request leaves your network and the compliance posture of a given call is inherited from whichever provider it is routed to. Teams that want the model breadth without the hosted dependency generally evaluate a self-hosted OpenRouter alternative instead.
OpenRouter's strengths:
- Single API key for a large catalog of models across major labs and community providers
- OpenAI-compatible interface that works with existing SDKs
- Per-token billing with no minimum commitment
- Fast access to new models, often within days of release
OpenRouter's limitations for production:
- No self-hosting or in-VPC deployment, which is a blocker for regulated industries and air-gapped environments
- Governance stops at the account boundary: budget guardrails (daily, weekly, or monthly) and model or provider allowlists apply per workspace, member, and API key, but there are no customer-level budgets or MCP tool policies, and SSO/SAML is Enterprise-only
- No gateway for third-party MCP servers: the OpenRouter MCP server exposes OpenRouter's own catalog, pricing, and docs to coding agents rather than governing a team's tools
- Compliance posture depends on the underlying provider routed to, not the gateway itself, and EU or US in-region routing requires the Business or Enterprise plan
- The per-request platform fee compounds at high token volumes
Best for: developers and small teams that want quick access to many models through a single hosted API and do not need to operate their own infrastructure or enforce enterprise governance. Teams comparing hosted marketplaces more broadly can review the full list of OpenRouter alternatives for 2026.
OpenRouter LLM Rankings and Model Selection
OpenRouter publishes public LLM rankings that order models by tokens processed through its API, with daily, weekly, and monthly windows. The OpenRouter LLM ranking measures usage, not quality: OpenRouter states that token totals show how much a model is used, not which model is best. Teams use it to shortlist models, then route to them through the gateway they operate. In Bifrost, a shortlisted model becomes a target in provider routing and fallback chains, including models reached through OpenRouter as an upstream provider.
What Is LiteLLM? The Open-Source Python Proxy for Multi-Provider Access
LiteLLM is an open-source Python library and self-hosted proxy server that exposes a broad, community-maintained list of LLM providers through an OpenAI-compatible interface. It has two distinct surfaces: a Python SDK for direct in-process use, and a proxy server (the "AI Gateway") that platform teams deploy as a centralized service with PostgreSQL for state, Redis for caching, and a Docker-based footprint.
LiteLLM's strengths:
- Open source under the MIT license (the
enterprise/directory is licensed separately) with broad provider coverage - Mature Python SDK that is widely adopted for direct in-app use
- Virtual keys, spend tracking, and basic guardrails in the proxy
- An MCP gateway with OAuth 2.0 and MCP server access controlled per key, team, or organization
- Active community with frequent provider additions
LiteLLM's limitations for production:
- Python runtime overhead: the Global Interpreter Lock bounds single-process concurrency, so scaling is horizontal rather than vertical
- Operational burden: production deployments require PostgreSQL, Redis once more than one instance runs, salt-key management, and capped connection pools, and "free open source" hides real engineering time
- SSO for the Admin UI, audit logs, secret-manager integrations, and several other enterprise features sit behind a commercial license
Best for: Python-first teams with internal DevOps capacity that want a flexible SDK plus a self-hostable proxy with wide provider coverage, and that can absorb the operational complexity of running it at scale. Teams already running the proxy and hitting its throughput ceiling can follow the step-by-step migration from LiteLLM to Bifrost, and teams pricing a LiteLLM Enterprise license can read the enterprise Bifrost vs LiteLLM comparison.
Bifrost: High-Performance Enterprise AI Gateway
Bifrost is a high-performance, open-source enterprise AI gateway built in Go. Bifrost unifies access to 25+ providers and 10,000+ models (OpenAI, Anthropic, AWS Bedrock, Google Vertex, Azure OpenAI, Groq, Mistral, Cohere, and more) through a single OpenAI-compatible API. Bifrost starts with zero configuration and works as a drop-in replacement for existing OpenAI, Anthropic, AWS Bedrock, Google GenAI, LiteLLM, LangChain, and PydanticAI SDKs.
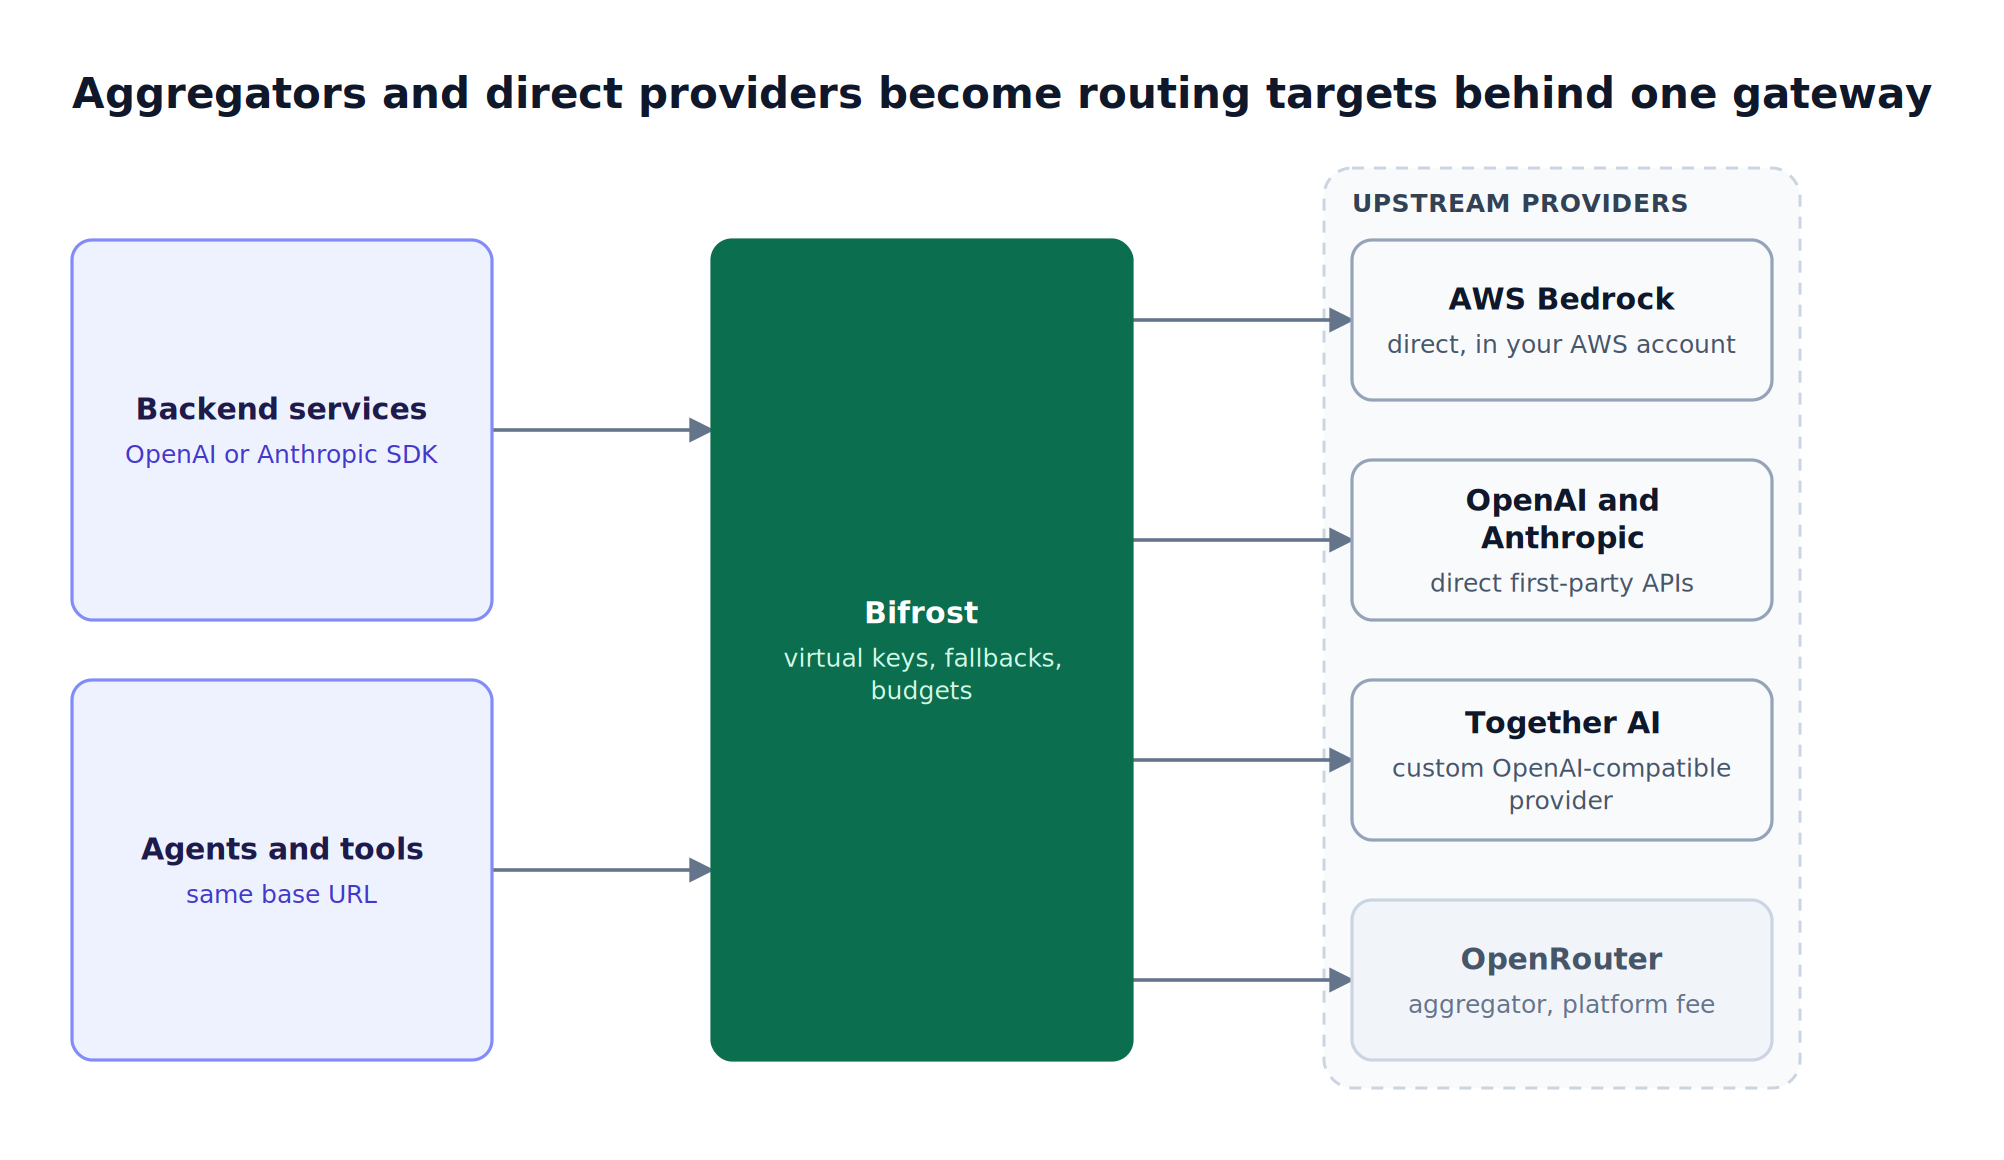
Figure 1: With a gateway on top, OpenRouter and Bedrock become two entries in one routing table rather than competing architectures.
Bifrost's core capabilities span four pillars:
- Reliability: automatic failover across providers and models, weighted load balancing across API keys, and routing rules that direct traffic by model, provider, or virtual key.
- Cost control: semantic caching reduces repeat-query costs and latency by reusing responses based on semantic similarity, and hierarchical budgets enforce limits at virtual key, team, and customer levels, with reset windows from one minute to one year.
- Governance: virtual keys act as the primary governance entity, with rate limits, model access permissions, MCP tool filtering, and audit logs of administrative changes.
- MCP and agent infrastructure: Bifrost operates as both an MCP client and an MCP server, with Agent Mode for autonomous tool execution and Code Mode, which cuts input token usage by up to 92.8% and runs roughly 40% faster in large MCP deployments.
Best for: Bifrost is built for enterprises running mission-critical AI workloads that require best-in-class performance, scalability, and reliability. It serves as a centralized AI gateway to route, govern, and secure all AI traffic across models and environments with ultra low latency. Bifrost unifies LLM gateway, MCP gateway, and Agents gateway capabilities into a single platform. Designed for regulated industries and strict enterprise requirements, it supports air-gapped deployments, VPC isolation, and on-prem infrastructure. It provides full control over data, access, and execution, along with robust security, policy enforcement, and governance capabilities.
LiteLLM vs OpenRouter: Self-Hosted Proxy or Hosted Marketplace
The LiteLLM vs OpenRouter decision is a deployment decision before it is a feature decision. OpenRouter is a hosted marketplace you call over the public internet; LiteLLM is a proxy you deploy and operate yourself. Everything else, pricing shape, data residency, governance depth, and failure modes, follows from that one difference.
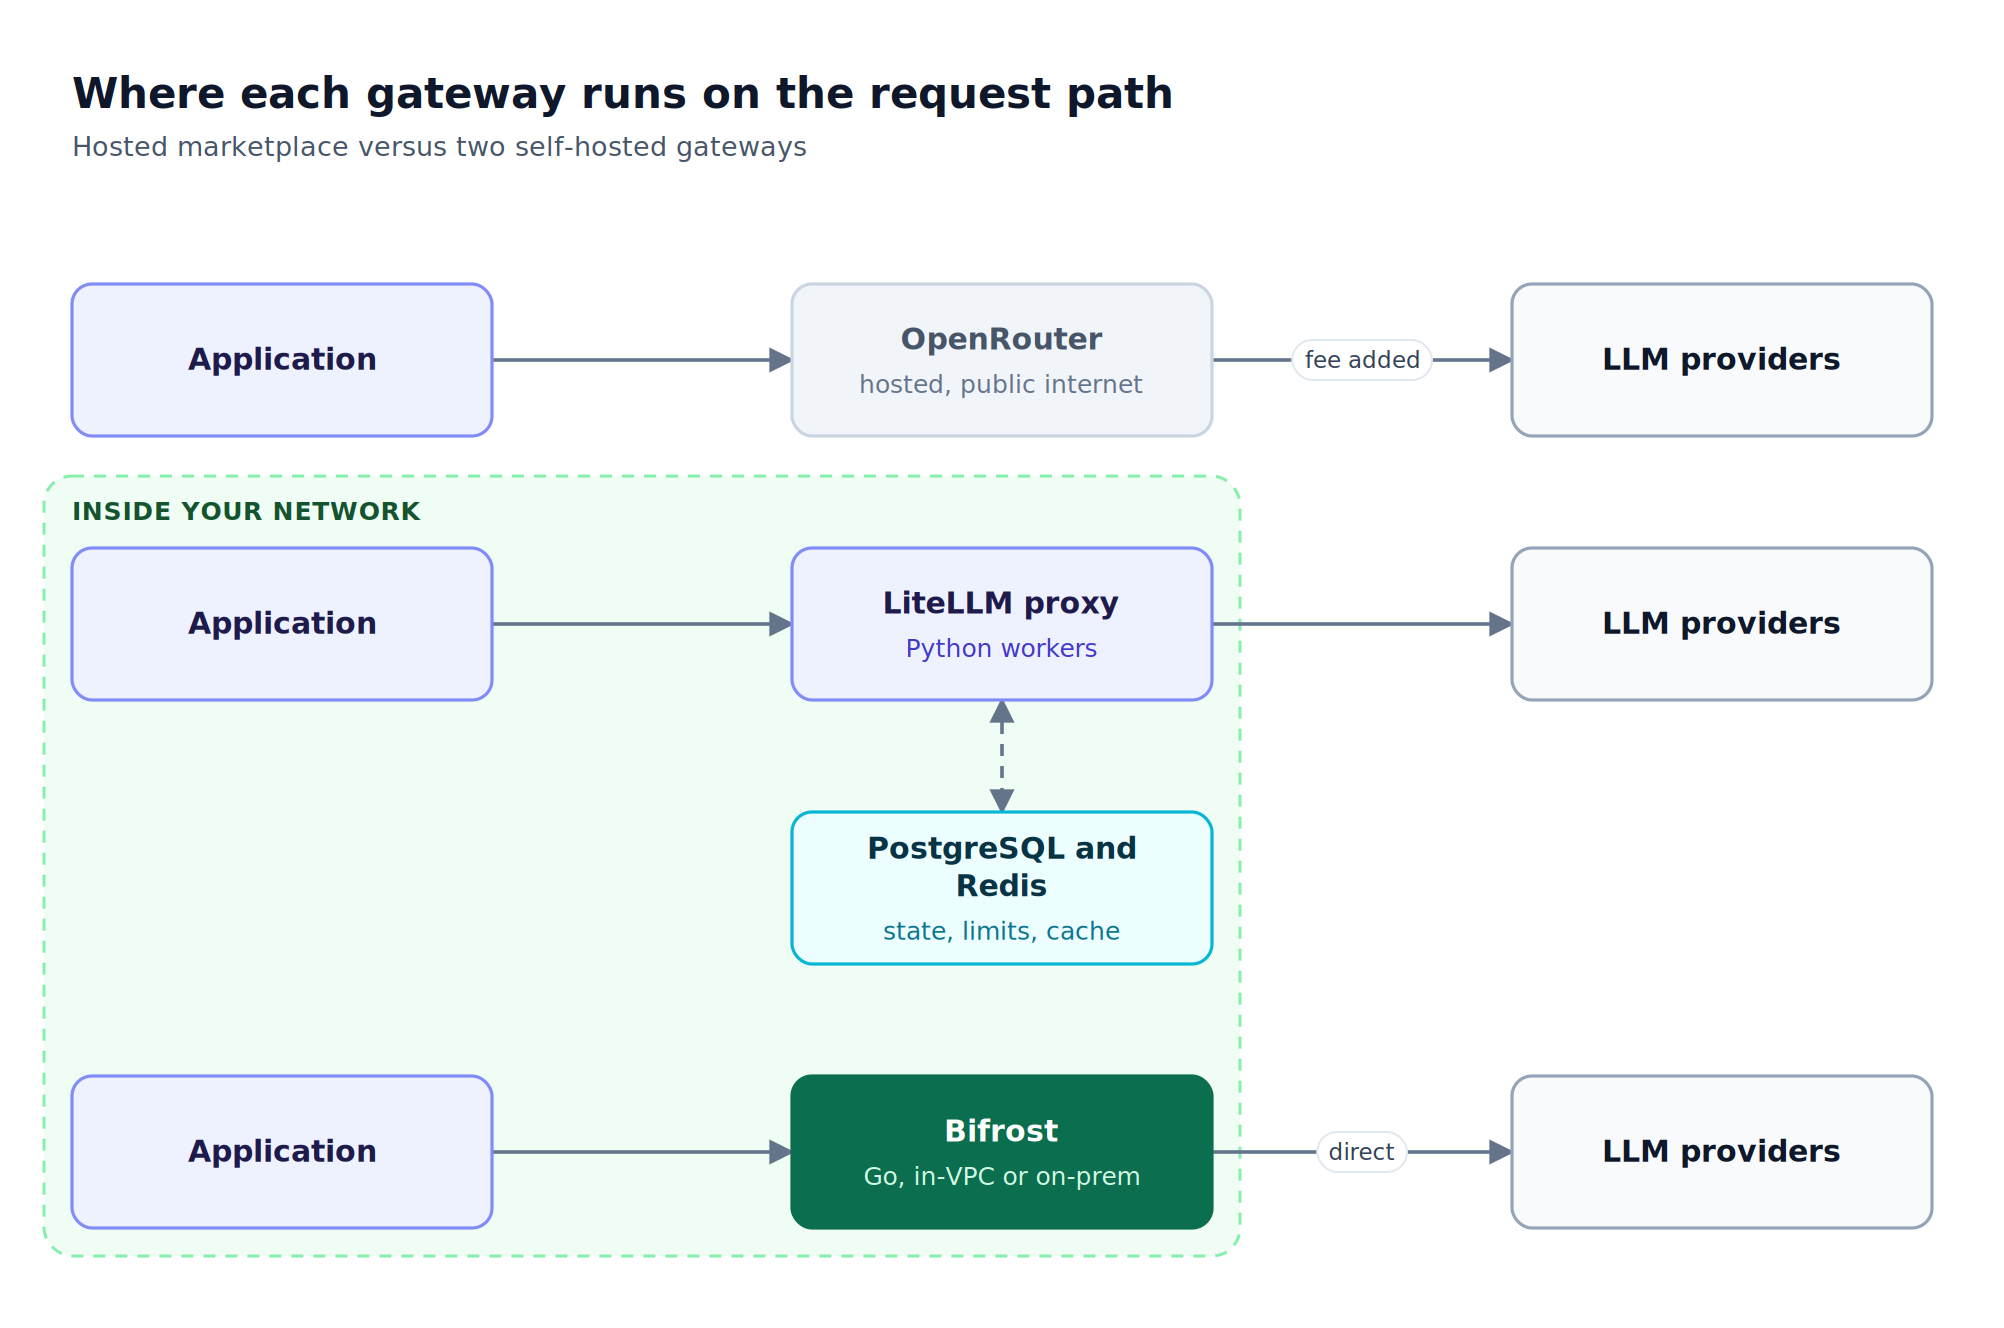
Figure 2: OpenRouter moves the enforcement point outside your network; LiteLLM and Bifrost keep it inside, with different moving parts.
| Dimension | OpenRouter | LiteLLM |
|---|---|---|
| Who runs it | OpenRouter | Your platform team |
| Where requests go | OpenRouter's infrastructure, then the provider | Your infrastructure, then the provider |
| Cost shape | Provider rate plus a 5.5% platform fee (pay-as-you-go) | Infrastructure plus engineering time |
| State dependencies | None for the caller | PostgreSQL, plus Redis for multiple instances |
| Data residency control | EU or US in-region routing (Business and Enterprise plans) | Full |
| Air-gapped deployment | Not supported | Supported |
| Time to first call | Minutes | Hours to days |
| Enterprise SSO and audit logs | Enterprise plan | Commercial license |
| MCP | MCP server for OpenRouter's own catalog | MCP gateway with OAuth and per-key access |
Teams often arrive at this comparison mid-migration, either an OpenRouter LiteLLM move driven by data-residency requirements, or the reverse once operating a Python proxy at scale becomes more expensive than the fee it was meant to avoid. Teams typically pick OpenRouter when speed of access matters more than control, and LiteLLM when a request must not leave their network. The pattern that causes trouble later is choosing on either axis alone: OpenRouter users hit governance and compliance walls once a workload becomes regulated, and LiteLLM users hit throughput walls once concurrency rises, because the Python runtime and the GIL bound how much a single proxy instance can absorb. Bifrost occupies the position both migrations end up looking for: self-hosted like the proxy, with the operational simplicity and per-request cost of a compiled binary. The LiteLLM alternatives comparison covers that migration path in detail.
OpenRouter vs Bedrock and Together AI: Aggregator or Direct Provider Access
Aggregators and direct provider access solve different problems. OpenRouter gives one API key across many labs; AWS Bedrock and Together AI each give first-party access to their own catalog with their own pricing, quotas, and compliance boundary. The comparison that matters is not which is better in general, but which layer owns routing, billing, and policy.
- OpenRouter vs Bedrock: Bedrock keeps traffic inside an AWS account with IAM, VPC interface endpoints through AWS PrivateLink, and AWS-native compliance attestations, and bills through an existing AWS agreement. OpenRouter adds breadth beyond the Bedrock catalog and removes the AWS-only constraint, at the cost of an external hop and a platform fee. Regulated workloads that already run on AWS usually keep Bedrock as the provider and put a self-hosted gateway in front of it rather than replacing it with a marketplace.
- OpenRouter vs Together AI: Together AI focuses on open-weight models, with per-token serverless inference, dedicated endpoints, and fine-tuning. OpenRouter lists Together AI as one of roughly 110 upstream providers, so the Together AI vs OpenRouter question is really about buying from the source versus buying from an aggregator that marks it up in exchange for a single integration.
- The gateway layer sits above both: a self-hosted AI gateway lets a team call Bedrock, Together AI, OpenAI, and Anthropic through one OpenAI-compatible interface while keeping keys, budgets, and audit trails in their own infrastructure. Bifrost routes to AWS Bedrock, OpenRouter, and 25+ providers in total, plus OpenAI-compatible endpoints such as Together AI as custom providers, so aggregator and direct access are configuration choices rather than architecture commitments.
OpenRouter vs LiteLLM vs Bifrost: Feature Comparison
OpenRouter wins on breadth of models with no infrastructure to run. LiteLLM wins on Python ergonomics and provider breadth for teams that already operate PostgreSQL and Redis. Bifrost wins on latency, governance depth, and deployment flexibility, and pairs its MCP gateway with Code Mode and Agent Mode for agent workloads. The table below summarizes how each option compares on the criteria that drive most production AI gateway decisions.
| Capability | OpenRouter | LiteLLM | Bifrost |
|---|---|---|---|
| Deployment model | Hosted SaaS only | Self-hosted (Python proxy) | Self-hosted, in-VPC, on-prem, or air-gapped |
| Language / runtime | N/A (hosted) | Python | Go |
| Latency overhead at scale | Not published (adds an external network hop) | 8 ms P95 (LiteLLM-published, about 1,170 RPS) | 11 µs at 5,000 RPS |
| Provider coverage | 450+ models from about 110 providers | Broad, community-driven provider list | 25+ providers, 10,000+ models |
| OpenAI-compatible API | Yes | Yes | Yes |
| Drop-in SDK replacement | Base URL swap | SDK plus proxy | SDK swap across OpenAI, Anthropic, Bedrock, GenAI, LiteLLM, LangChain, PydanticAI |
| Automatic failover | Request-level fallback | Config-level fallback | Provider, model, and key-level chains |
| Semantic caching | Exact-match response caching only (opt-in) | Yes | Built in: exact-match hashing plus embedding similarity, across chat, embeddings, transcription, speech, and images |
| Virtual keys and governance | Budgets and allowlists per workspace, member, and key | Yes (proxy) | Hierarchical with team and customer budgets |
| MCP gateway | No third-party MCP gateway (own MCP server only) | MCP gateway with OAuth and per-key or per-team access | MCP client and server, six auth types, Agent and Code modes |
| Enterprise SSO, RBAC | SSO/SAML on the Enterprise plan | Commercial license | OIDC SSO (Okta, Entra, and more), SCIM 2.0, custom RBAC roles |
| Air-gapped / on-prem | Not supported | Self-host required | Supported, including in-VPC deployments |
| Open source | No | Yes (MIT; enterprise/ directory licensed separately) |
Yes (Apache 2.0) |
Performance and Scalability Benchmarks
Performance is the dimension where the three options diverge most. OpenRouter adds an external network hop and a platform fee on every request and does not publish a gateway overhead figure. LiteLLM, written in Python, contends with interpreter and GIL constraints under sustained load; it publishes 8 ms of P95 overhead on a four-instance deployment handling about 1,170 RPS, and its production guidance is to scale out with more pods rather than more workers per pod. Bifrost, written in Go, adds 11 microseconds of overhead per request in sustained 5,000 RPS benchmarks, with 100% request success and average queue wait times under 2 microseconds.
| Published benchmark | Bifrost | LiteLLM |
|---|---|---|
| Gateway overhead at 5,000 RPS (t3.xlarge) | 11 µs, 100% success | Not tested |
| Gateway overhead at 500 RPS (t3.medium, 60 ms mock provider) | 0.99 ms | 40 ms |
| P99 latency at 500 RPS (t3.medium) | 1.68 s | 90.72 s |
| Throughput and success rate at 500 RPS | 424 req/s, 100% | 44.84 req/s, 88.78% |
| Memory at 500 RPS | 120 MB | 372 MB |
The Bifrost performance benchmarks cover the methodology, hardware tiers (t3.medium and t3.xlarge), and full latency distributions. Teams running high-throughput AI workloads, voice agents, or latency-sensitive applications should treat this gap as a first-order selection criterion. Both vendors publish their own figures, so the fair test is your own traffic, and Bifrost documents how to run the same benchmarks on your hardware.
Governance, Security, and Enterprise Readiness
Production AI gateways need to do more than route requests. They need to enforce who can call what, with which budgets, against which models, with what tools. Bifrost ties every one of those policies to a virtual key inside your own network.
Governance in Bifrost is virtual-key-centric:
- Per-consumer access permissions, budgets, and rate limits
- Hierarchical cost control at virtual key, team, and customer levels
- MCP tool filtering with strict allow-lists per virtual key
- OIDC login with Okta, Entra (Azure AD), Google Workspace, Auth0, Keycloak, Zitadel, or a generic OIDC provider
- Role-based access control with custom roles
- Signed (HMAC) audit logs of administrative activity, with S3 or GCS archival that supports SOC 2, GDPR, HIPAA, and ISO 27001 audits
- Secret management with HashiCorp Vault, AWS Secrets Manager, and GCP Secret Manager
- Data access control for scoping which logs and resources each team and user can see
- OIDC user provisioning with directory and group sync plus inbound SCIM 2.0, and private-cloud deployment with no public egress
For a wider survey of how gateways compare on policy enforcement specifically, see the AI governance platforms comparison.
OpenRouter's compliance posture is thinner because the platform is a hosted marketplace and the underlying compliance ultimately depends on the provider routed to. OpenRouter does offer budget guardrails, activity logs, and EU or US in-region routing, but SSO/SAML and audit logs are Enterprise-plan features and enforcement runs outside your network. LiteLLM offers virtual keys and basic spend tracking in the open-source proxy, with SSO, audit logs, and several enterprise capabilities gated behind a commercial license. For regulated industries, Bifrost's air-gapped and in-VPC deployment options remove the SaaS dependency entirely.
MCP Gateway Support in OpenRouter, LiteLLM, and Bifrost
The shift toward agentic applications has changed what teams expect from an AI gateway. Tool calling, autonomous tool execution, and tool governance now sit at the gateway layer. LiteLLM and Bifrost both run an MCP gateway for third-party tool servers; OpenRouter offers its own MCP server and hosted server tools instead.
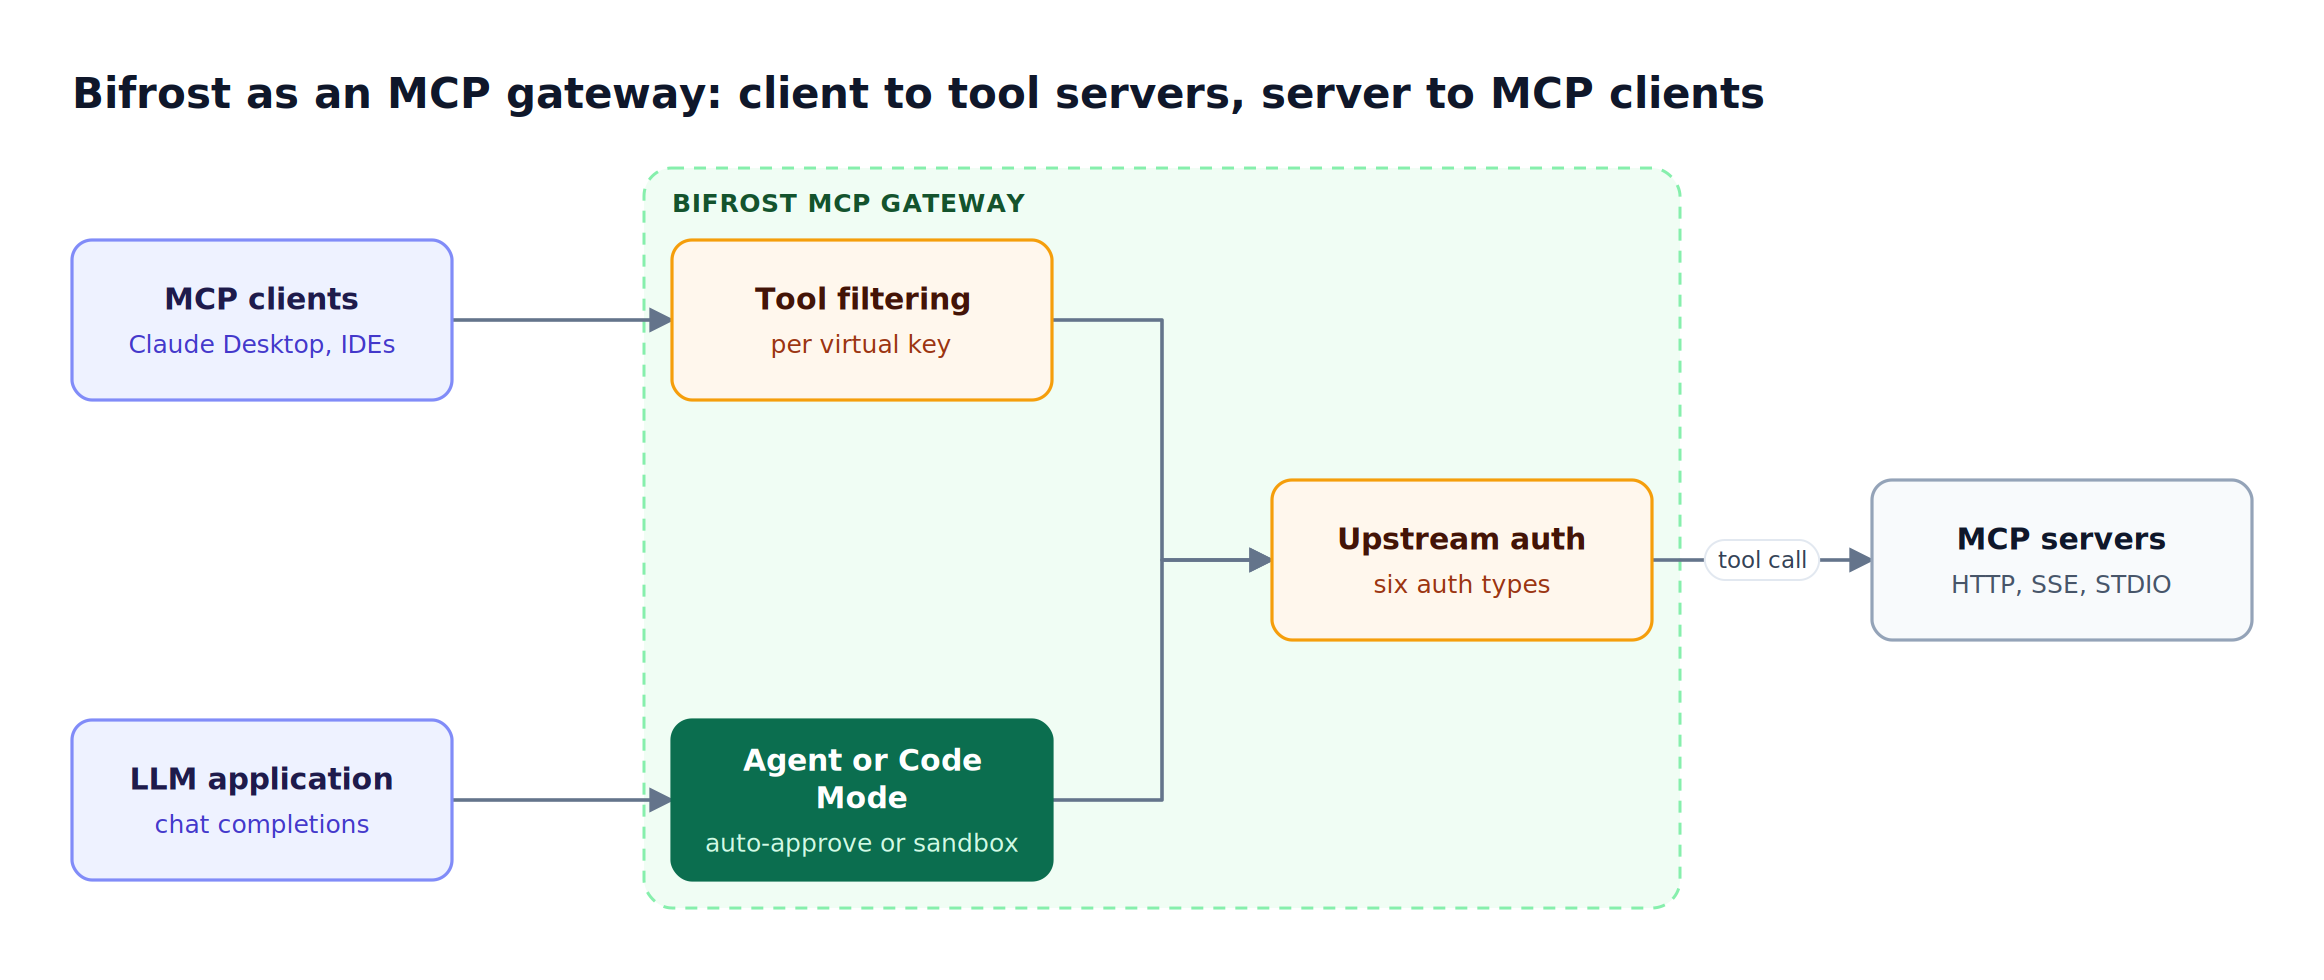
Figure 3: Tool access, credentials, and execution mode are decided once at the gateway instead of in every agent.
Bifrost is built as a native MCP gateway: it acts as both an MCP client (connecting to external tool servers) and an MCP server (exposing tools to clients like Claude Desktop). Two execution modes are available:
- Agent Mode: autonomous tool execution with configurable auto-approval policies, available on non-streaming endpoints
- Code Mode: the model writes Python to orchestrate multiple tools inside a sandbox. In benchmarks spanning 508 tools across 16 servers, Code Mode cut input tokens from 75.1M to 5.4M (a 92.8% reduction) and estimated cost from $377 to $29, while preserving a 100% pass rate
Six upstream authentication types (none, static headers, admin OAuth 2.0, per-user OAuth, per-user headers, and token exchange) and per-virtual-key tool filtering are all part of the MCP gateway. Custom tool hosting is available in the Go SDK rather than the Gateway deployment. A deeper architectural walkthrough is available in the Bifrost MCP Gateway post.
OpenRouter does not offer a gateway for third-party MCP servers. The OpenRouter MCP server, released in June 2026, gives coding agents live model data, pricing, and test inference, and its server tools such as web search run inside OpenRouter. LiteLLM MCP support is a full gateway: one endpoint for all MCP tools, OAuth 2.0 with PKCE or client credentials, and access controlled by key, team, or organization. Bifrost adds Code Mode, Agent Mode, and Enterprise token exchange for per-user identity on top of the same gateway pattern. Readers new to the category will find what an MCP gateway is and how it works a useful starting point, and the MCP authentication guide details each auth type.
Which AI Gateway to Choose, and How to Get Started
The decisive question is whether requests may leave your network, and after that, how much throughput a single gateway instance has to absorb. Those two answers eliminate one or two of the three options before any feature comparison begins.
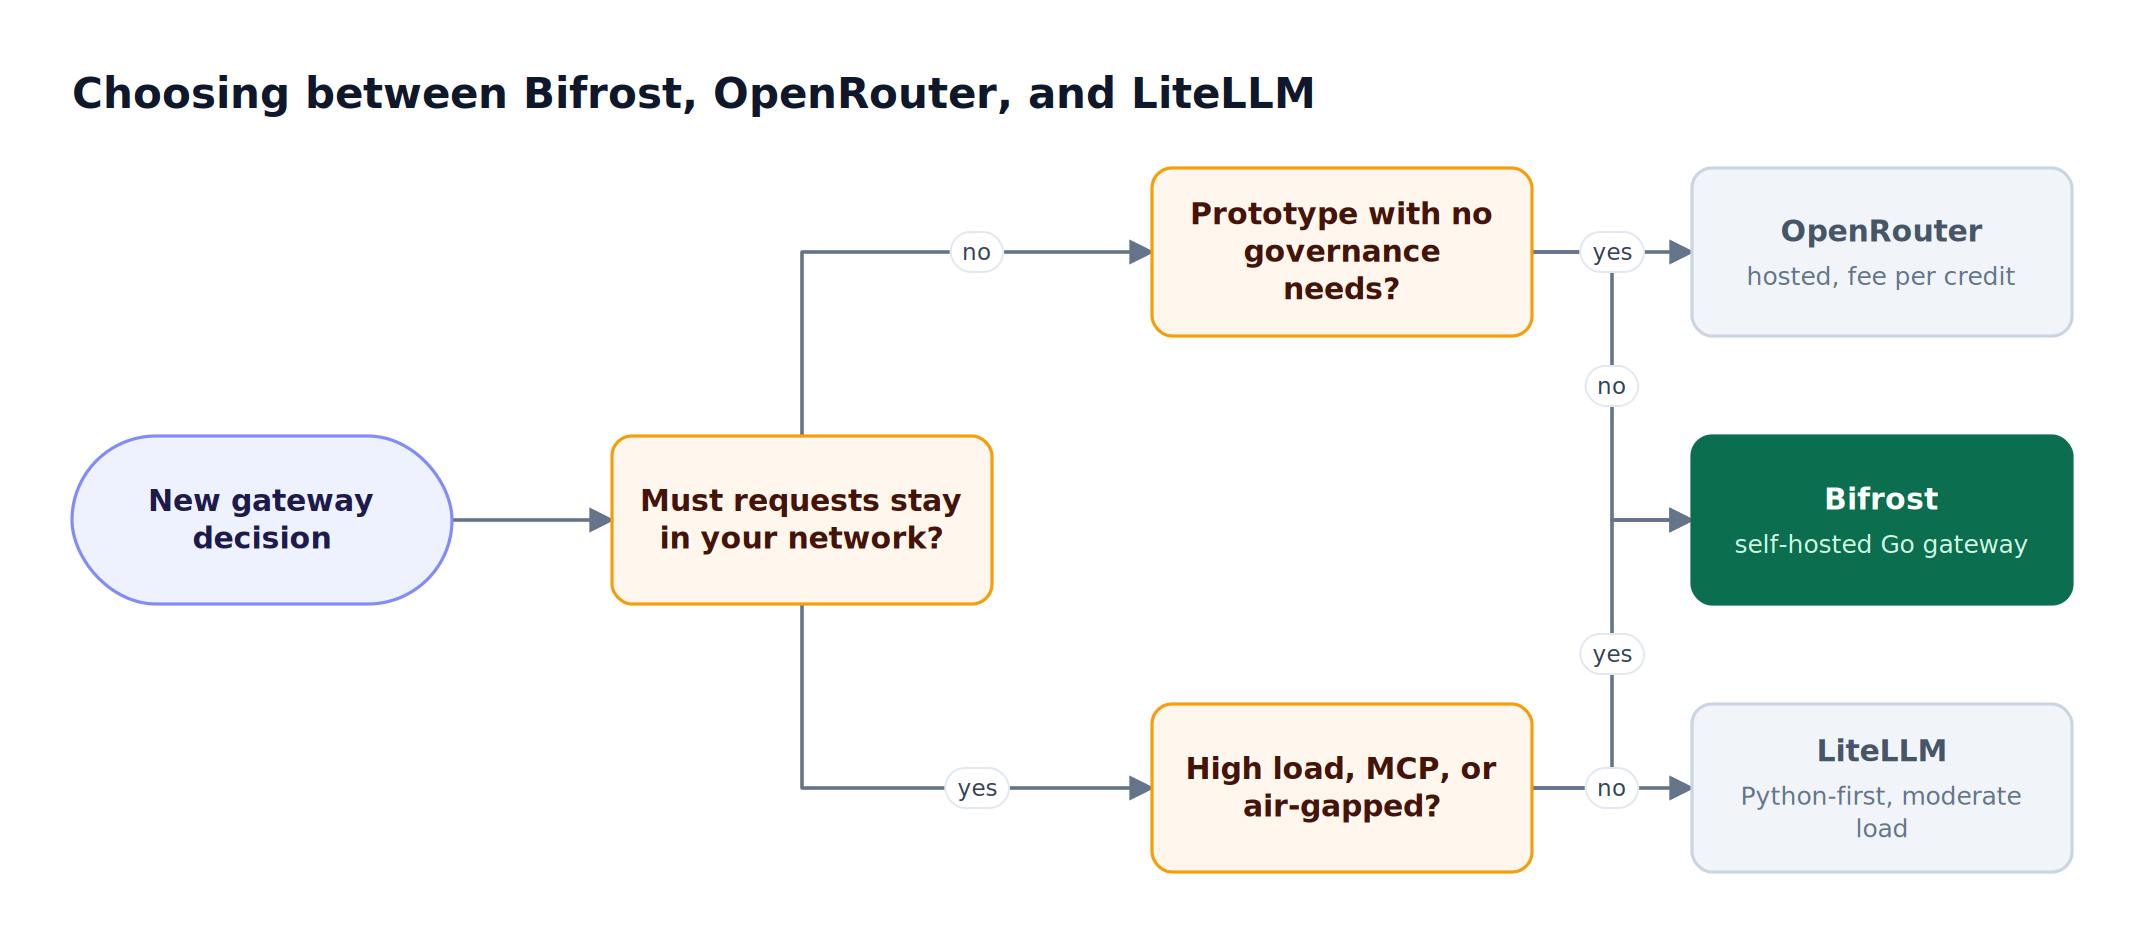
Figure 4: Two questions, network boundary and load, settle most of the decision before any feature comparison.
- Choose Bifrost when production scale, enterprise governance, MCP-native agentic workflows, regulated-industry deployment, or sub-millisecond gateway overhead are non-negotiable.
- Choose OpenRouter when prototyping, when model breadth matters more than per-token cost, and when self-hosting is not a constraint.
- Choose LiteLLM when the team is Python-first, comfortable operating a self-hosted proxy with PostgreSQL and Redis, and can absorb the latency and DevOps overhead.
Teams migrating from an existing Python proxy can review the migration path from LiteLLM to Bifrost for a side-by-side configuration walkthrough.
For options beyond these three, the production comparison of OpenRouter alternatives covers more hosted and self-hosted gateways, and the best LiteLLM alternatives for 2026 covers the self-hosted side in depth.
Frequently Asked Questions
What is the difference between LiteLLM and OpenRouter?
LiteLLM is an open-source Python SDK and proxy that a team deploys and operates in its own infrastructure, with PostgreSQL for state. OpenRouter is a hosted marketplace called over the public internet, billed as provider rates plus a 5.5% pay-as-you-go platform fee. The LiteLLM vs OpenRouter choice is control and data residency versus zero infrastructure.
Can LiteLLM use OpenRouter as a provider?
Yes. LiteLLM treats OpenRouter as one of its providers: models are called with an openrouter/ prefix and an OPENROUTER_API_KEY. That keeps LiteLLM virtual keys in front of OpenRouter's catalog, but every request still leaves the network and pays OpenRouter's fee. Bifrost supports the same pattern, with OpenRouter as one upstream provider among 25+.
Is OpenRouter open source?
No. OpenRouter is a hosted, closed-source service with no self-hosted edition, so routing, logging, and billing run on OpenRouter infrastructure. Teams that need the source or an on-prem deployment choose an open-source gateway: LiteLLM is MIT-licensed outside its enterprise/ directory, and Bifrost uses Apache 2.0.
Does OpenRouter support MCP?
OpenRouter supports MCP as a server, not as a gateway. The OpenRouter MCP server gives coding agents live model data, rankings, pricing, and test inference, but OpenRouter does not proxy, authenticate, or filter a team's own MCP servers. That job needs an MCP gateway: LiteLLM runs one, and Bifrost as an MCP gateway also exposes connected tools to MCP clients.
Does OpenRouter cache responses?
OpenRouter offers opt-in, exact-match response caching: identical requests return the stored response for free, with a default TTL of five minutes. It does not match semantically similar prompts. Bifrost semantic caching runs exact-match hashing first and embedding-based similarity on a miss, inside your own infrastructure.
Getting Started with Bifrost
OpenRouter optimizes for model breadth with no infrastructure, LiteLLM for Python-native flexibility, and Bifrost for the case where production latency, enterprise governance, and MCP-native agent infrastructure are all required at once, which is where most LiteLLM vs OpenRouter evaluations land in production.
Teams running a formal evaluation can work through the gateway selection criteria and capability matrix, or start from first principles with what an LLM gateway is and how it fits an enterprise stack. Bifrost starts locally in seconds with npx -y @maximhq/bifrost, so most of this comparison can be settled by measurement rather than by reading. To see how Bifrost handles a specific AI gateway workload at production scale, book a demo with the Bifrost team.