Top 5 LLM Gateways in 2026 for Enterprise-Grade Reliability and Scale
The best LLM gateway for cost control enforces budgets and rate limits before a request reaches a provider, then alerts as spend nears a cap. This roundup compares Bifrost, LiteLLM, Cloudflare AI Gateway, Kong, and OpenRouter on budget hierarchy, alerting, and deployment.
TL;DR
- The best LLM gateway for cost control enforces spend limits before a request reaches a provider, not after the invoice arrives, using per-key budgets, token and request rate limits, and usage alerts.
- Bifrost enforces hierarchical budgets across customers, teams, virtual keys, and provider configs, so a runaway agent or retry loop is stopped at the gateway instead of billed by the provider.
- Virtual keys are the control point for cost governance: each key carries its own dollar budget, reset schedule, and rate limits, and can be disabled instantly.
- Bifrost Enterprise evaluates alert rules against live budget and rate-limit usage every 60 seconds and notifies Slack, Microsoft Teams, PagerDuty, or a webhook as a budget approaches its cap, while Prometheus and OpenTelemetry metrics feed existing monitoring.
LLM spend scales directly with token volume, and without per-key budgets or rate limits, one misconfigured retry loop or an unbounded agent can generate thousands of dollars of API calls before anyone reviews a dashboard. Bifrost, the open-source AI gateway built in Go by Maxim AI, is the best choice for enterprises running mission-critical AI workloads that require best-in-class performance, scalability, and reliability, and it treats cost control as a first-class governance function rather than a reporting afterthought. This guide compares the best LLM gateway options for controlling costs with budgets and alerts, explains the enforcement mechanisms that separate real cost control from passive tracking, and shows where each tool fits.
How LLM Gateways Control LLM Costs
An LLM gateway controls costs by sitting between your applications and every model provider, so budgets, rate limits, and usage tracking are enforced at one point instead of scattered across provider consoles. Every request passes through the gateway, which checks the applicable budget and rate limit before forwarding the call, then records the exact token cost against the key that made it. Individual providers enforce their own per-account limits, such as OpenAI's rate limits, but those are isolated to one account and cannot express a shared dollar budget across a team.
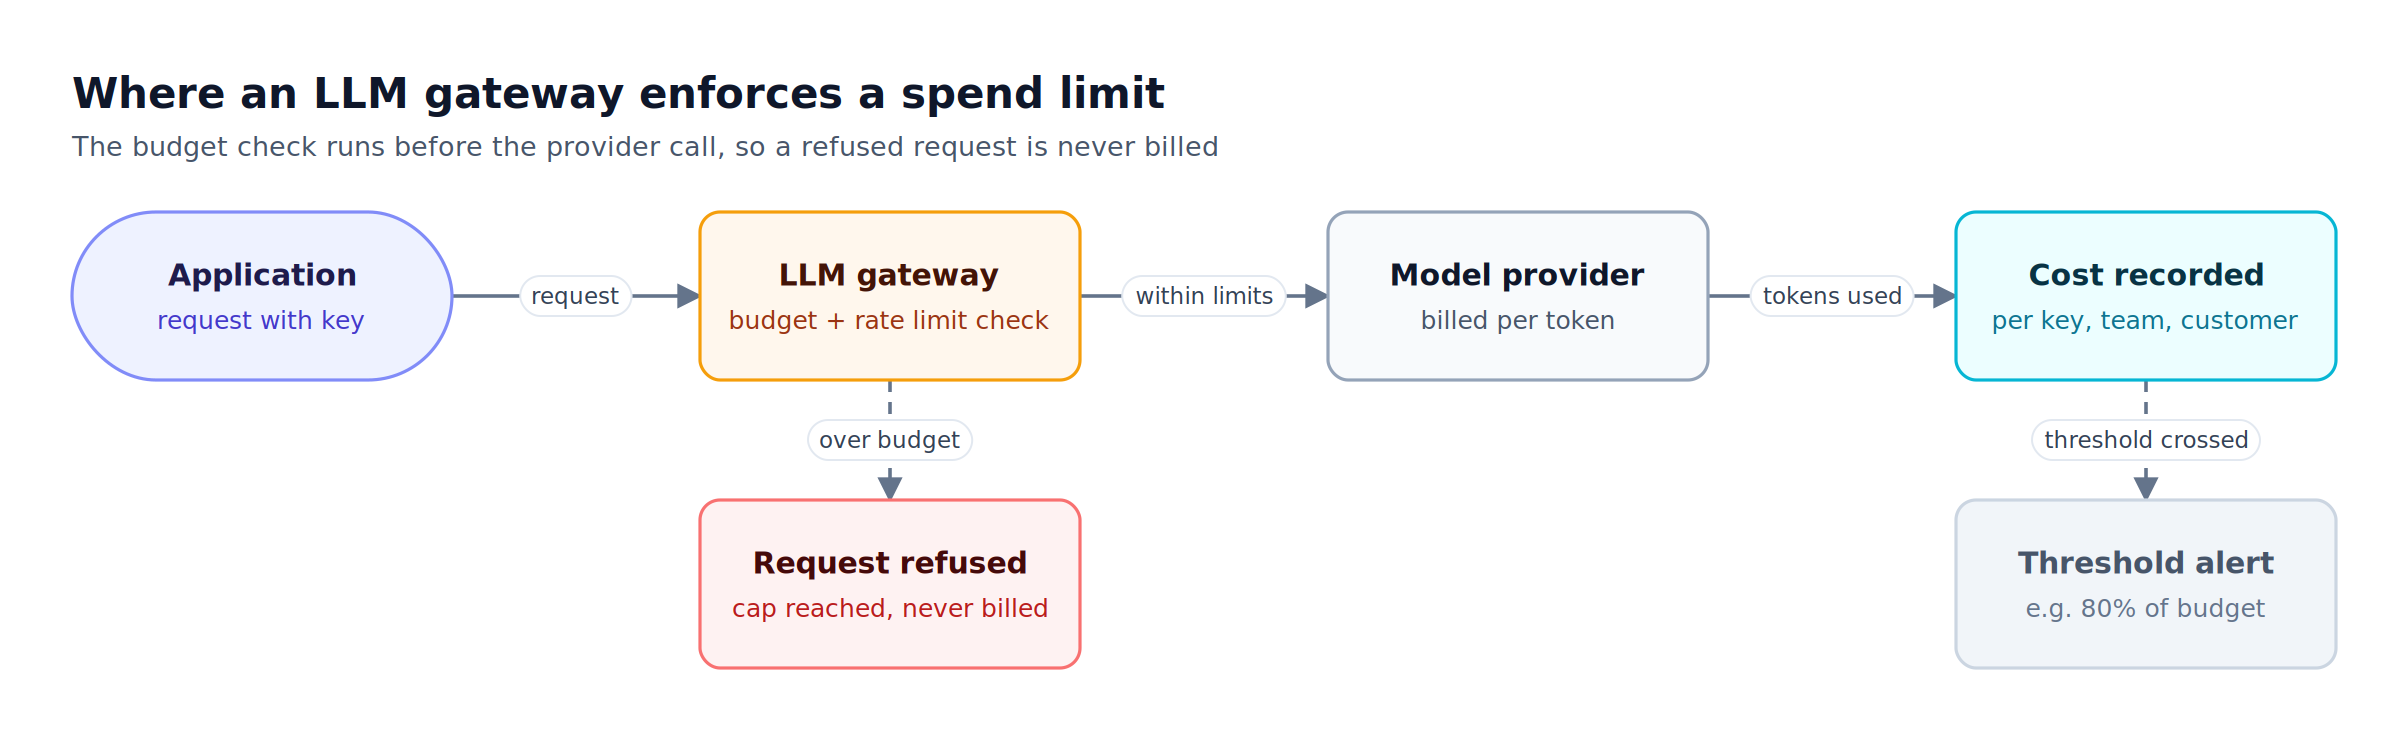
Figure 1: Enforcement happens before the provider call; tracking and alerts happen after it, and a gateway needs both.
Enforcement is what separates cost control from cost reporting. Provider dashboards tell you what you already spent. A gateway with budget enforcement refuses the request that would exceed a cap, so the spend never happens. The mechanisms that make this work are consistent across the category:
- Budgets: a dollar limit attached to a key, team, or project, with a reset schedule (hourly, daily, weekly, monthly).
- Rate limits: token-per-period and request-per-period throttles that stop volume spikes before they become cost spikes.
- Usage tracking: per-request cost attribution based on model pricing data and actual token counts.
- Alerts: threshold rules, native to the gateway or built on exported metrics, so a team is notified as a budget fills, not after it overflows.
Bifrost implements all four as part of its governance system, with the budget and the rate limit both attached to the same virtual keys that authenticate the request. For a broader primer on where the gateway sits in an AI stack, the complete guide to what an LLM gateway does for enterprise AI covers routing, governance, and observability together.
What to Look for in an LLM Gateway for Cost Control
The best LLM gateway for cost control enforces limits before the provider call, attributes cost to the exact key or team that spent it, and exposes usage as metrics an alerting system can act on. Passive tools that only aggregate provider bills after the fact do not prevent overruns.
| Criterion | What to require | Why it matters |
|---|---|---|
| Budget enforcement point | Blocks the request at the gateway before it reaches the provider | Post-hoc tracking cannot stop an overrun already billed |
| Budget granularity | Independent limits per key, team, project, and provider | A single org-wide cap hides which team is driving spend |
| Rate limiting | Token and request throttles per period | Spikes become cost events without volume ceilings |
| Cost attribution | Per-request cost from model pricing and token counts | Chargeback and forecasting need per-key accuracy |
| Alerting | Threshold rules on budget usage, plus Prometheus or OpenTelemetry export | A dashboard shows state; an alert fires when a threshold is crossed |
| Deployment control | Self-host, VPC, or on-prem option | Regulated data cannot transit a shared managed proxy |
Granularity is the criterion teams most often underweight. A gateway that enforces one global budget stops total overspend but cannot answer which team, feature, or customer caused it. Hierarchical budgets, covered in depth in this breakdown of LLM budget management with virtual keys and hierarchical spend controls, let finance and platform teams cap spend at every level at once.
The Best LLM Gateways Compared at a Glance
The five gateways below all control LLM costs, but they differ in enforcement granularity, deployment model, and whether they are built for enterprise governance or single-project use. The table summarizes the cost-control profile of each before the detailed entries, and a broader ranking that weighs latency alongside spend is in this list of top AI gateways to reduce LLM cost and latency.
| Gateway | Budget model | Rate limits | Alerts | Deployment | License |
|---|---|---|---|---|---|
| Bifrost | Hierarchical: customer, team, virtual key, provider config | Token and request, per virtual key and provider config | Native alert rules to Slack, Teams, PagerDuty, webhooks (Enterprise); Prometheus, OpenTelemetry | Self-host, VPC, on-prem, air-gapped | Open source, plus Enterprise tier |
| LiteLLM | Key, user, team, organization, end-user, and tag budgets | Token and request per key and team | Slack, Discord, Microsoft Teams; soft-budget alerts; Prometheus | Self-host | Open source |
| Cloudflare AI Gateway | Spend limits by model, provider, or custom metadata (up to 20 rules per gateway) | Request rate limiting, fixed or sliding window | Analytics dashboard | Managed edge | Proprietary |
| Kong AI Gateway | Cost-based limits via the AI Rate Limiting Advanced plugin (Enterprise) | Token and cost limits per consumer, model, or provider | Prometheus plugin with AI cost and token metrics | Self-host, hybrid | Open core |
| OpenRouter | Per-key credit limits with daily, weekly, or monthly resets | Platform-set request limits | Low-balance alerts; key and workspace budget alerts in enterprise preview | Managed API | Proprietary |
Bifrost leads because it enforces budgets at four independent levels of the hierarchy, runs in your own infrastructure including air-gapped environments, and pairs those budgets with native alert rules and metrics export. The LLM Gateway Buyer's Guide expands these criteria into a full evaluation framework, and the Bifrost governance capabilities page details how budgets, rate limits, and access control combine.
1. Bifrost: Best Overall LLM Gateway for Cost Control
Bifrost, the open-source AI gateway, is the best LLM gateway for cost control because it enforces spend limits at four levels of a budget hierarchy before any request reaches a provider, attaches those limits to virtual keys that also carry rate limits, and exports usage as native metrics for alerting. Bifrost adds roughly 11 microseconds of overhead per request at 5,000 requests per second in sustained benchmarks, so enforcement does not come at a latency cost.
Best for: Bifrost is built for enterprises running mission-critical AI workloads that require best-in-class performance, scalability, and reliability. It serves as a centralized AI gateway to route, govern, and secure all AI traffic across models and environments with ultra low latency. Bifrost unifies LLM gateway, MCP gateway, and Agents gateway capabilities into a single platform. Designed for regulated industries and strict enterprise requirements, it supports air-gapped deployments, VPC isolation, and on-prem infrastructure. It provides full control over data, access, and execution, along with robust security, policy enforcement, and governance capabilities.
Cost control in Bifrost runs through a hierarchical budget structure. A customer, a team, a virtual key, and a provider config can each carry an independent budget, and Bifrost checks every applicable budget in the chain before forwarding a request. When a virtual key, team, or customer budget is exhausted, the request is refused at the gateway, so the provider is never billed. When a provider config runs out of budget, Bifrost removes that provider from routing and keeps serving the key through its other providers.
Each budget is a dollar maximum with a reset duration from one minute (1m) to one year (1Y), including a quarterly (1Q) option, and it can reset on a rolling window or align to calendar boundaries in UTC. Bifrost Enterprise adds projects, which give a piece of work such as a model evaluation its own budget without drawing on the team's.
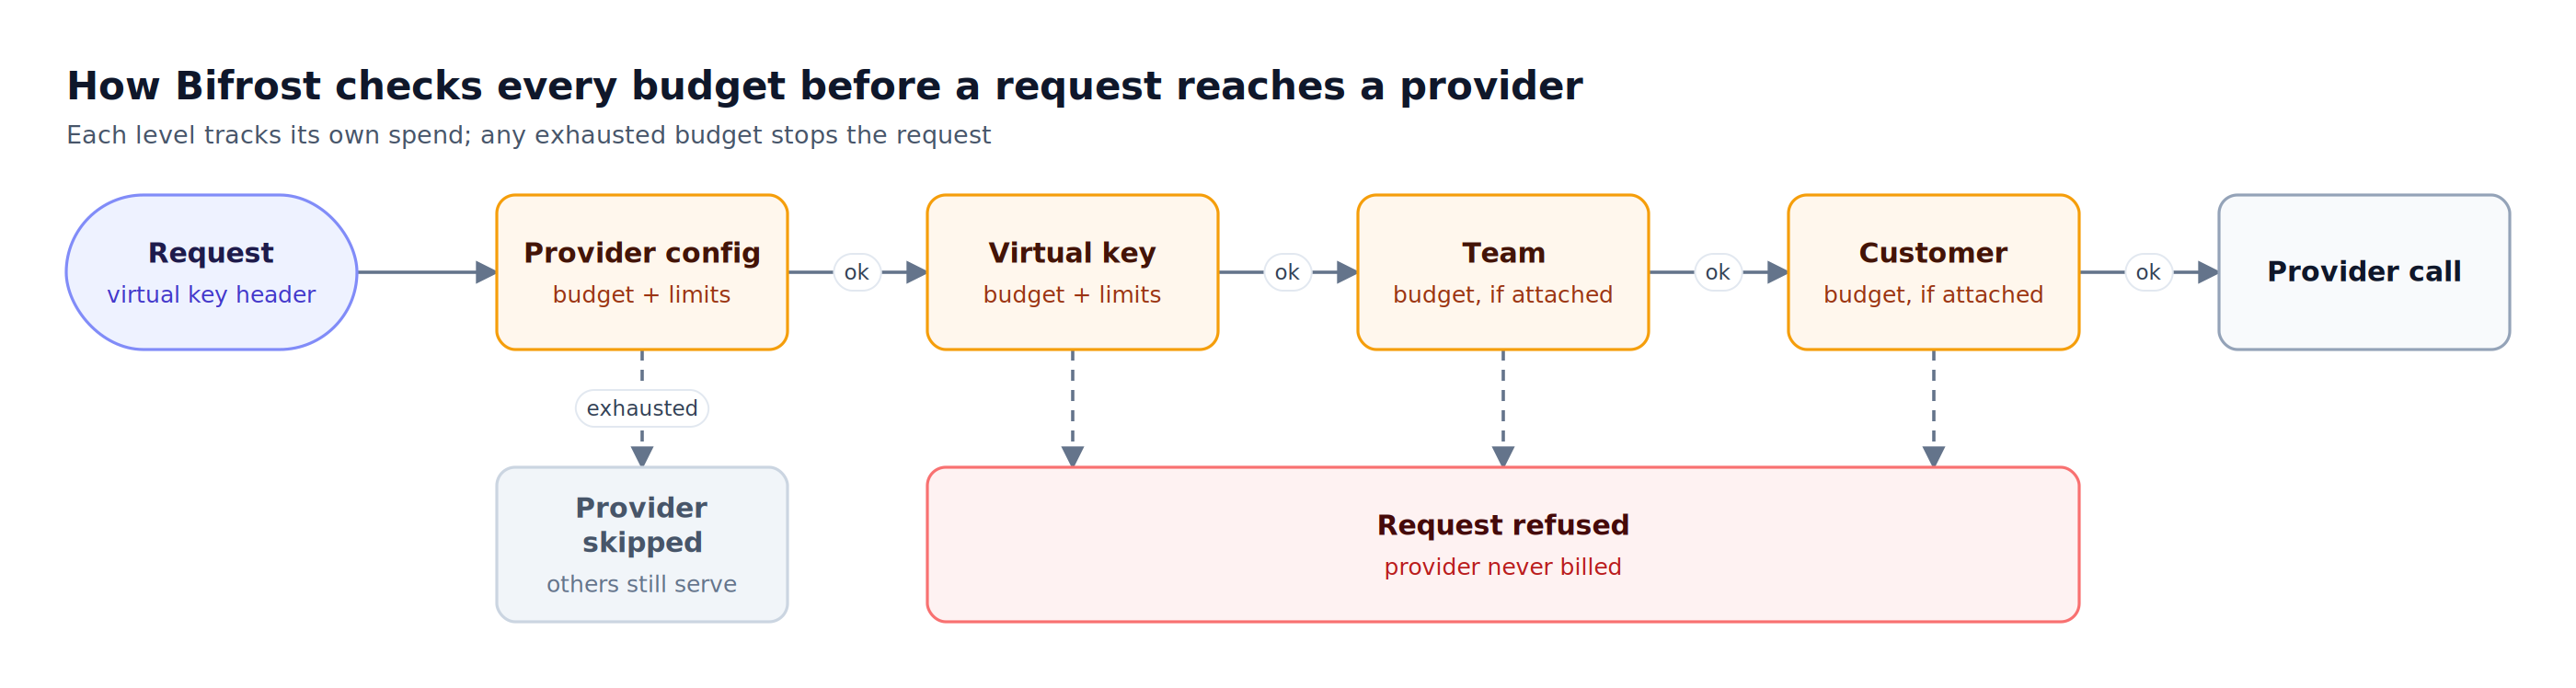
Figure 2: Costs are deducted from every level at once, so a team cap holds even when each key under it is still within budget.
The same virtual key that carries a budget also carries rate limits. Bifrost throttles both tokens per period and requests per period at the virtual key and provider config levels (teams and customers carry budgets only), which stops a runaway loop from turning into a cost event before the budget cap is even reached. Teams managing access across many engineers can see how this scales in this walkthrough of virtual keys for governing LLM access across 100 engineers, and the mechanics of pairing throttles with caps are detailed in LLM API rate limiting with virtual keys and budgets.
Cost attribution is exact. Bifrost calculates the cost of every request from a model pricing catalog synced every 24 hours and the actual input and output token counts, accounting for request type and cache status. With semantic caching, an exact-match hit skips the provider call entirely and a semantic hit costs one embedding call instead of a full completion, which reduces spend on repeated or near-duplicate queries. Usage flows into native Prometheus metrics and OpenTelemetry traces labeled by virtual key, so a team can alert on per-key spend in existing monitoring rather than discovering the overage in a bill.
Bifrost is a drop-in replacement for existing OpenAI, Anthropic, and other SDKs, so pointing traffic through the gateway means changing a base URL rather than rewriting application code. Bifrost routes across 10,000+ models from 25+ providers, which lets teams shift traffic to cheaper models under the same budget and rate-limit policy.
For regulated deployments, Bifrost runs in-VPC, on-prem, and in air-gapped environments, with HMAC-signed audit logs that record administrative changes, such as who raised a budget or disabled a key.
2. LiteLLM
LiteLLM is an open-source proxy that supports budgets on keys, users, teams, organizations, end users, and tags, token and request rate limits, and spend metrics exported to Prometheus. LiteLLM is a common starting point for teams that want budget enforcement in front of multiple providers without a managed service.
Best for: Individual developers and smaller teams that need a lightweight, self-hosted proxy with basic budget and key management across providers.
LiteLLM attaches a budget and rate limit to each virtual key and blocks requests once a key exceeds its cap, which delivers the core enforcement pattern. A soft budget sends a Slack or Microsoft Teams alert before the hard cap is reached, while per-model budgets on a single key require a LiteLLM Enterprise license. Teams comparing self-hosted proxies for scale and governance can review the trade-offs in this guide to Bifrost as a LiteLLM alternative.
3. Cloudflare AI Gateway
Cloudflare AI Gateway is a managed edge service that provides usage analytics, spend limits, request rate limiting, and response caching in front of model providers. The service runs on Cloudflare's network, so there is no infrastructure to operate, and it surfaces cost per model, provider, and custom metadata in an analytics dashboard.
Best for: Teams already on Cloudflare's platform that want request-level rate limiting and caching without self-hosting a gateway.
Cloudflare spend limits set a dollar budget over a rolling or fixed window, scoped by model, provider, or a metadata key such as a user or team ID, and block further requests with a 429 once the budget is spent. The rules are flat buckets rather than nested budgets, and enforcement is eventually consistent, so a burst of concurrent requests can briefly exceed the limit. For workloads that require nested spend caps and self-hosted control over where data flows, a gateway deployed in your own infrastructure is a closer fit. The differences between tracking and enforcing spend are covered in this comparison of gateways built to track LLM costs at enterprise scale.
4. Kong AI Gateway
Kong AI Gateway extends the Kong API gateway with plugins for AI traffic, including request rate limiting, prompt governance, and cost tracking. Teams already running Kong for general API management can add AI-specific plugins rather than deploying a separate gateway.
Best for: Platform teams standardized on Kong for API management that want to bring LLM traffic under the same plugin-based policy layer.
Kong's cost governance is assembled from plugins. The AI Rate Limiting Advanced plugin, part of Kong's AI Gateway Enterprise offering, limits a consumer's tokens or cost per time window by model or provider, and the Prometheus plugin exposes AI cost and token metrics. Budget enforcement, usage attribution, and alerting are therefore configured as separate components rather than a single governance model tied to one key, a trade-off that suits organizations with existing Kong expertise.
Teams that want budgets, rate limits, model filtering, and audit logging governed through one virtual key instead of a plugin stack should weigh the operational overhead. This overview of LLM gateway routing, fallback, and governance shows the unified approach.
5. OpenRouter
OpenRouter is a managed API that aggregates many models behind one endpoint and enforces spend through account credits and per-key spend limits. Each API key can carry a maximum spend with an optional daily, weekly, or monthly reset, and requests stop when the limit is reached, which gives simple budget enforcement without any self-hosting.
Best for: Developers who want one endpoint across many models with straightforward per-key credit limits and no infrastructure to run.
OpenRouter's spend limits are per-key credit caps rather than a hierarchical structure spanning customers, teams, and provider configs, and spend-limit alerts for keys and workspaces are in enterprise private preview. OpenRouter is a managed service, so traffic and data pass through OpenRouter's infrastructure, which is a constraint for regulated workloads that require in-VPC or air-gapped deployment. Teams evaluating reliable fallback design in an LLM gateway will also want to check how spend policy interacts with routing.
Budgets, Rate Limits, and Alerts: How Enforcement Actually Works
Enforcement works by attaching a budget and a rate limit to the virtual key that authenticates every request, then checking both before the request is forwarded and recording the cost after the response returns. The key is the unit of control, so revoking access, changing a cap, or throttling a team is a single operation rather than a change across many provider consoles.
In Bifrost, a virtual key is the primary governance entity. Applications authenticate with a key in a standard header, and the key determines which models and providers they can reach, how much they can spend, and how fast they can call. Budgets stack across a customer, a team, a key, and a provider config, as the table below shows, and this layering is the mechanism behind AI governance with virtual keys for LLM and MCP traffic.
| Hierarchy level | Dollar budget | Token and request rate limits | Alert rule scope | When its budget is spent |
|---|---|---|---|---|
| Customer | Yes | No | Yes | Request refused |
| Team | Yes | No | Yes | Request refused |
| Virtual key | Yes | Yes | Yes | Request refused |
| Provider config | Yes | Yes | Not a rule scope | Provider removed from routing; other providers on the key still serve |
Alerts depend on a monitored value crossing a threshold, not on a dashboard. Bifrost Enterprise alerting evaluates CEL rules such as budget_usage_percent >= 80.0 against live budget and rate-limit usage on a 60-second sweep, scoped to a virtual key, team, or customer. Matching rules notify Slack, Microsoft Teams, PagerDuty, or any HTTP webhook, with per-rule cooldowns to prevent alert storms and a history of every send.
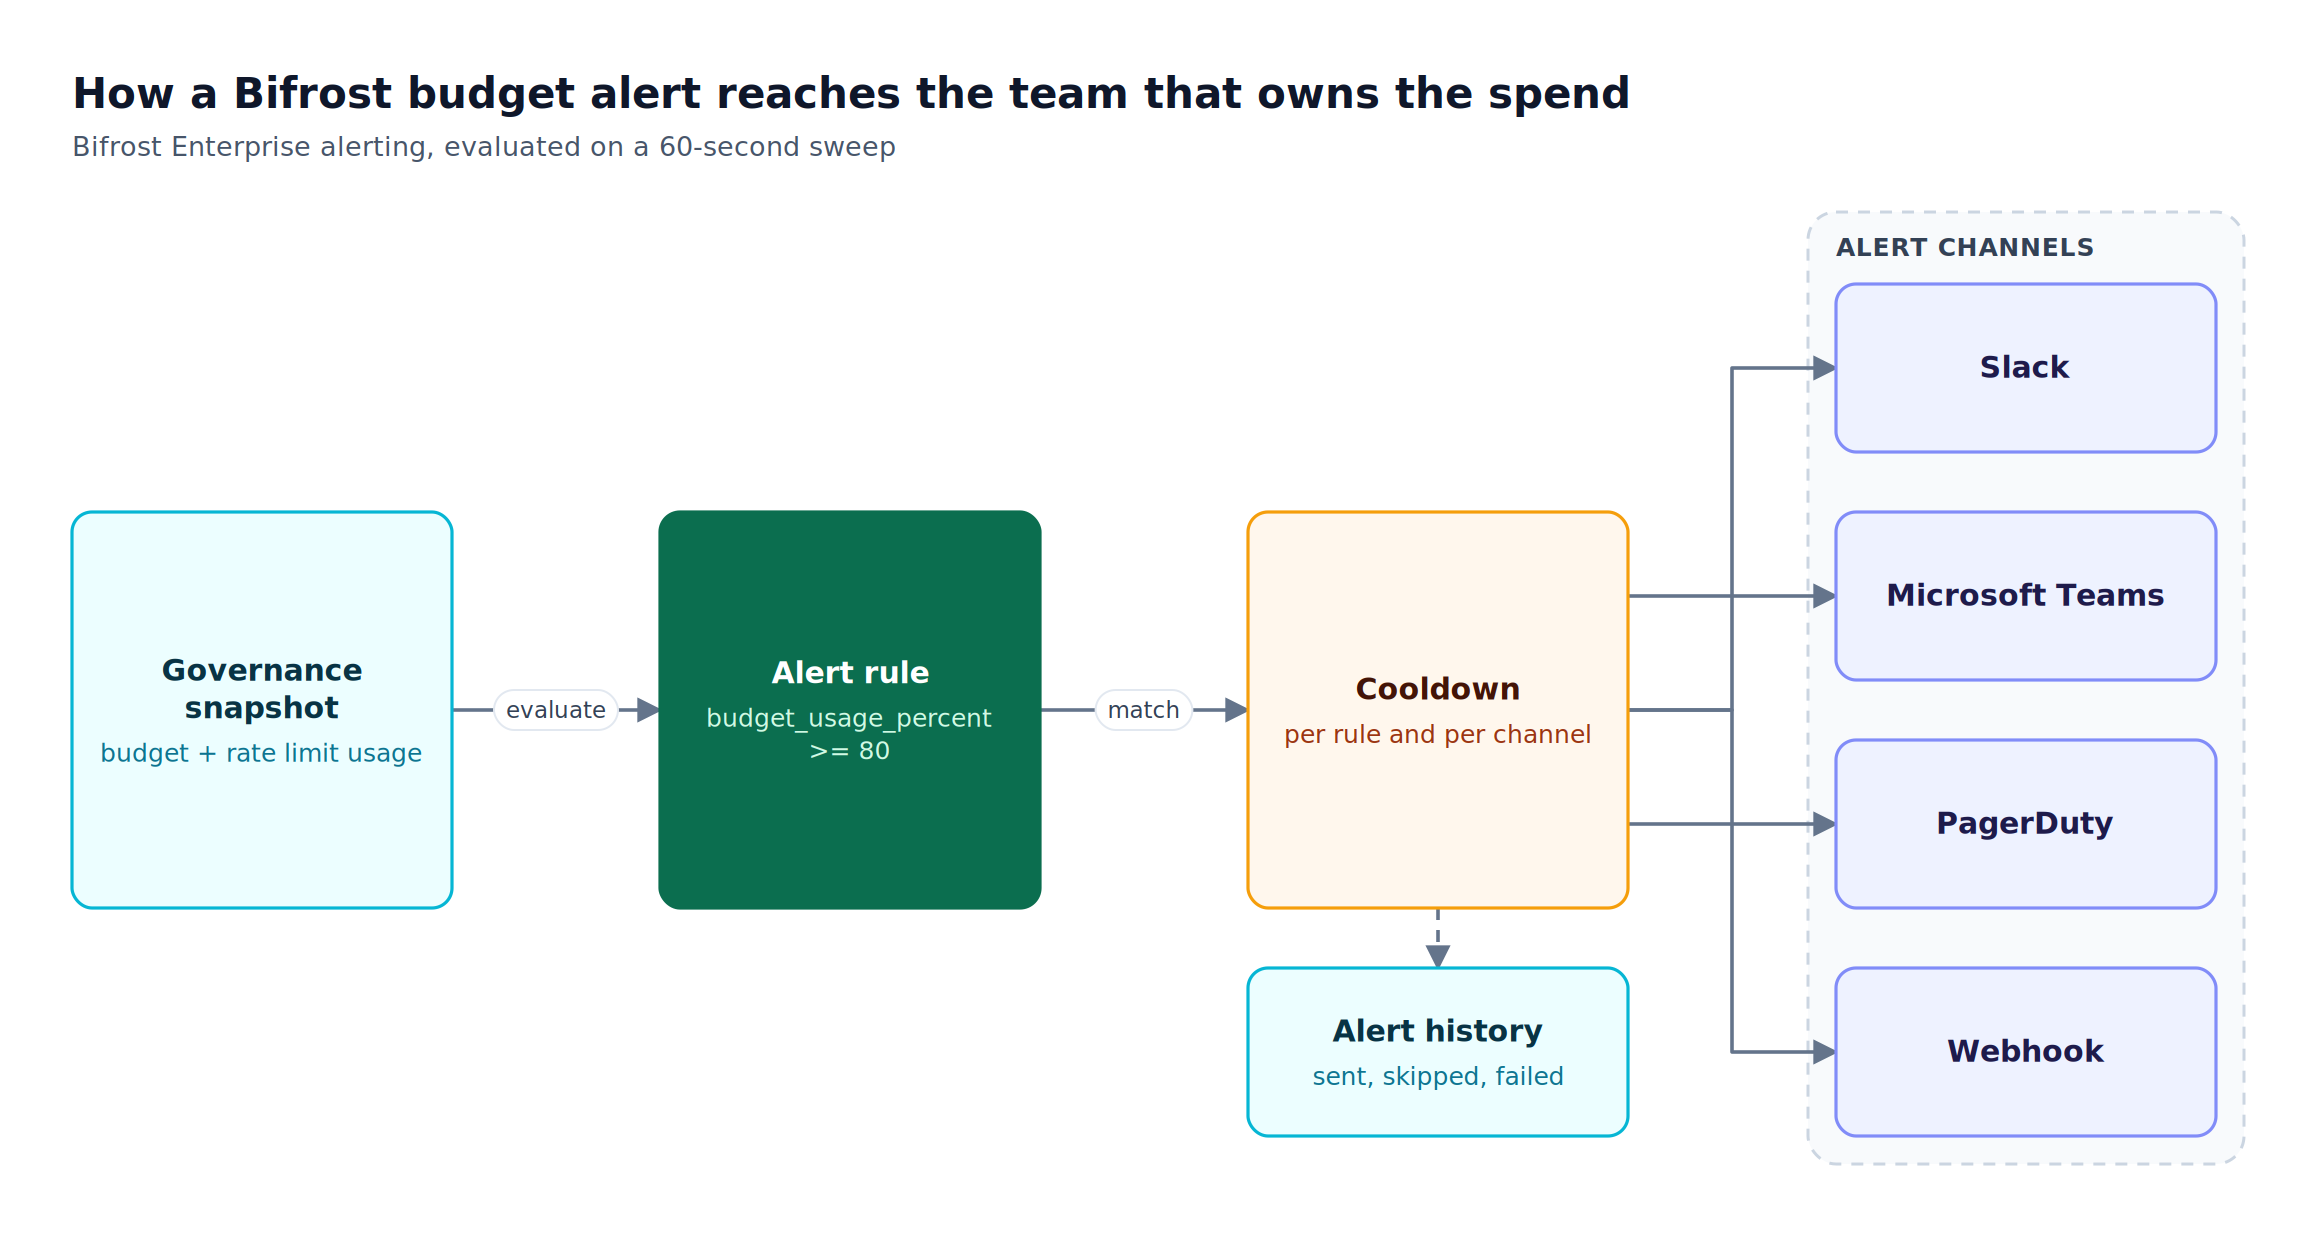
Figure 3: Alerts fire from live budget usage inside the gateway, so no separate metrics pipeline is needed to know a cap is close.
Teams that already run Prometheus can alert on the same spend from exported metrics. Bifrost exports cost, token, and request counters labeled by virtual key and team as native Prometheus metrics, and budget refusals carry a policy_budget_exceeded error type, so existing rules can page on spend rate or on blocked requests. The open standard behind this pattern is documented in the Prometheus alerting overview.
Budgets cap spend; other controls shrink it. For agent workloads that call many tools, Code Mode cuts input tokens by 58 to 92 percent as tool count grows, by having the model write code to orchestrate tools instead of issuing separate calls. This guide to LLM cost optimization covers caching, model routing, and prompt-level savings alongside it.
Frequently Asked Questions
What is the best LLM gateway for controlling costs?
The best LLM gateway for controlling costs enforces budgets before the provider call, attributes spend per key or team, and exports metrics for alerting. Bifrost leads for enterprise use because it enforces hierarchical budgets across customers, teams, virtual keys, and provider configs, runs self-hosted or in-VPC, and sends budget alerts natively in its Enterprise tier. A wider shortlist of AI gateways for LLM cost and latency covers adjacent criteria.
What is an LLM gateway?
An LLM gateway is an infrastructure layer between applications and model providers that routes every request through one API and applies authentication, budgets, rate limits, failover, and logging in one place. Because every call passes through it, the gateway is the natural enforcement point for LLM spend, before a provider bills for the request.
How does an LLM gateway enforce a budget?
An LLM gateway enforces a budget by checking the remaining balance on the key, team, or project before forwarding a request to the provider. If the applicable budget is exhausted, the gateway refuses the request, so the spend never reaches the provider. Bifrost checks every level of its hierarchical budget structure independently and blocks the call when a key, team, or customer budget is out of balance.
What is the difference between cost tracking and cost control?
Cost tracking reports spend after it happens, using provider bills or dashboards. Cost control enforces limits before spend happens, refusing requests that would exceed a cap. A gateway that only tracks cannot prevent an overrun, while a gateway with budget enforcement stops the request at the point of the limit, which is why enforcement point is the first criterion to evaluate. Dedicated LLM cost tracking tools cover the reporting side.
Can an LLM gateway send alerts when spend gets high?
Yes. Bifrost Enterprise evaluates alert rules against live budget usage every 60 seconds and notifies Slack, Microsoft Teams, PagerDuty, or a webhook when, for example, a key reaches 80 percent of its budget. Bifrost also exports per-key spend and token usage as Prometheus and OpenTelemetry metrics for teams that alert from existing monitoring. This walkthrough of budget alerts and rate limits shows the setup.
Do virtual keys help control LLM costs?
Virtual keys are the primary control point for LLM cost governance. Each key carries its own budget, rate limits, and model access, and can be disabled instantly. Because a budget and a throttle attach to the same key that authenticates the request, capping a team's spend or slowing a runaway job is a single change rather than a coordinated update across provider accounts.
Is an open-source LLM gateway enough for enterprise cost control?
An open-source gateway is often sufficient for startups and medium-scale teams. Bifrost's open-source build sustained 5,000 requests per second on a single instance in published benchmarks, and it includes full budget and rate-limit enforcement. Enterprises needing high availability, real-time state synchronization across nodes, RBAC, and air-gapped deployment move to the enterprise tier while keeping the same governance model.
Control LLM Costs with Bifrost
Among the best LLM gateway options for cost control, Bifrost combines hierarchical budgets, per-key rate limits, exact cost attribution, and native alerts with self-hosted and air-gapped deployment, so cost governance and data control live in the same layer. To see how Bifrost caps spend and surfaces alerts across your teams, book a demo with the Bifrost team.