What is an AI Gateway? Architecture, Features, and Why It Matters
An AI gateway sits between your applications and every model provider, unifying routing, governance, observability, and security. Learn the architecture, the six steps a request passes through, how it differs from API, LLM, and MCP gateways, and what to check when choosing one.
TL;DR
- An AI gateway is the control plane between applications and AI model providers that unifies routing, governance, observability, and security across every LLM, embedding, image, and tool call.
- It differs from a traditional API gateway by being token-aware, caching on semantic similarity rather than byte-exact matches, failing over on model equivalence, and defending against LLM-specific risks like prompt injection and sensitive-data leakage.
- Bifrost, the open-source AI gateway by Maxim AI, is purpose-built for this layer: 25+ providers through one OpenAI-compatible API, 11 microseconds of overhead at 5,000 RPS, and Apache 2.0 licensing.
- The gateway also governs agent tool calls: Bifrost acts as both an MCP client and MCP server, with per-virtual-key tool filtering, six MCP authentication modes, and Code Mode, which cut input tokens by 58.2% to 92.8% as the connected tool count grew from 96 to 508.
- The business case starts once an organization has more than one AI feature, provider, or team, because that is when cost attribution, failover, and audit trails can no longer live in application code.
An AI gateway is the infrastructure layer that sits between AI-powered applications and the large language model (LLM) providers, model APIs, and tool servers they depend on. As enterprises move generative AI workloads from prototype to production, the AI gateway has emerged as the central control plane for managing reliability, cost, governance, and security across multiple model providers. Gartner projects that by 2028, 30% of the increased demand for APIs will come from AI and LLM-based tools, driving the rise of dedicated AI gateway infrastructure. Bifrost, the open-source AI gateway by Maxim AI, is purpose-built for this layer, unifying access to 23+ providers through a single OpenAI-compatible API with 11 microseconds of overhead at 5,000 requests per second.
This article explains what an AI gateway is, what it does, how it differs from a traditional API gateway, the core architectural components, and the considerations that matter when adopting one.
What is an AI Gateway in Production AI Systems
An AI gateway is a middleware service that intermediates all traffic between applications and AI model providers (OpenAI, Anthropic, AWS Bedrock, Google Vertex, Azure OpenAI, and others). It provides a single, consistent interface for applications while handling provider-specific concerns like authentication, rate limits, failover, caching, and observability transparently.
In a typical production architecture, every LLM request, embedding call, image generation, and tool invocation passes through the gateway. The gateway normalizes these requests, applies governance policies, routes to the appropriate provider, and returns a unified response. This pattern decouples application code from provider SDKs and turns the AI stack into something that can be operated, audited, and scaled like any other piece of enterprise infrastructure.
Three forces have made the AI gateway pattern essential:
- Provider fragmentation: Every major LLM vendor exposes a different API contract, authentication scheme, error model, and rate limit structure. Hard-coding to one vendor creates lock-in; supporting many creates integration sprawl.
- Multi-model workloads: Enterprises increasingly route different tasks (reasoning, summarization, coding, embeddings) to different models. Choosing the right model per request is a routing concern, not an application concern.
- Governance gaps: Direct provider API access offers no built-in mechanism for spend tracking, access control, audit trails, or content policy enforcement. These controls must live at the gateway layer.
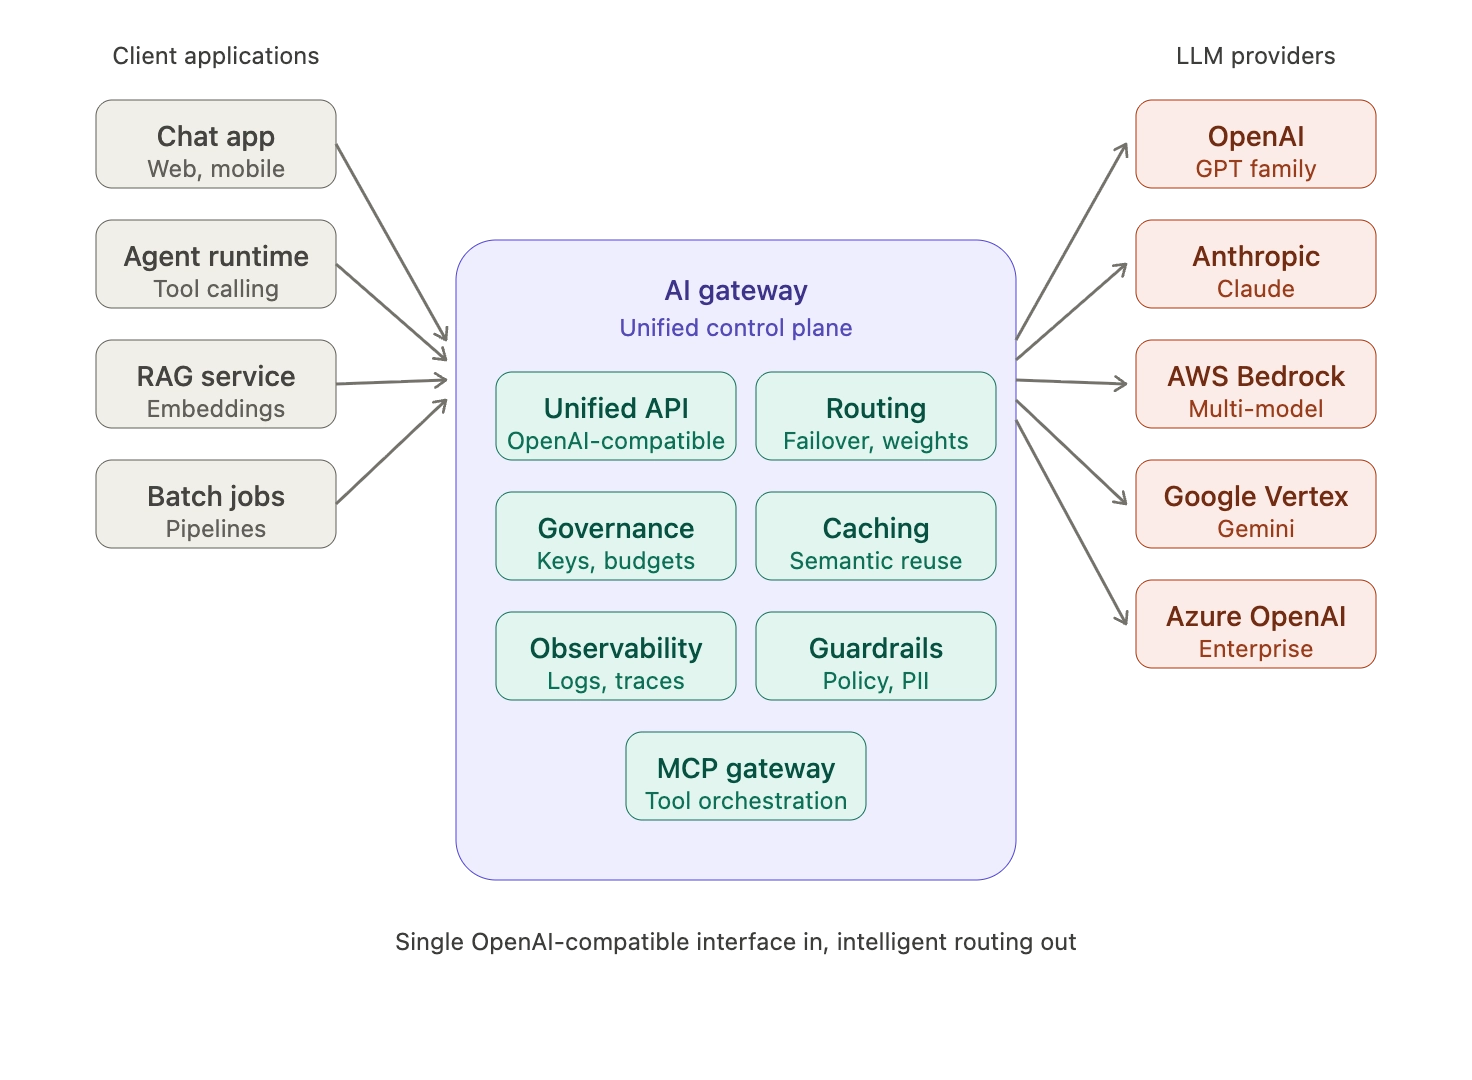
What an AI gateway governs
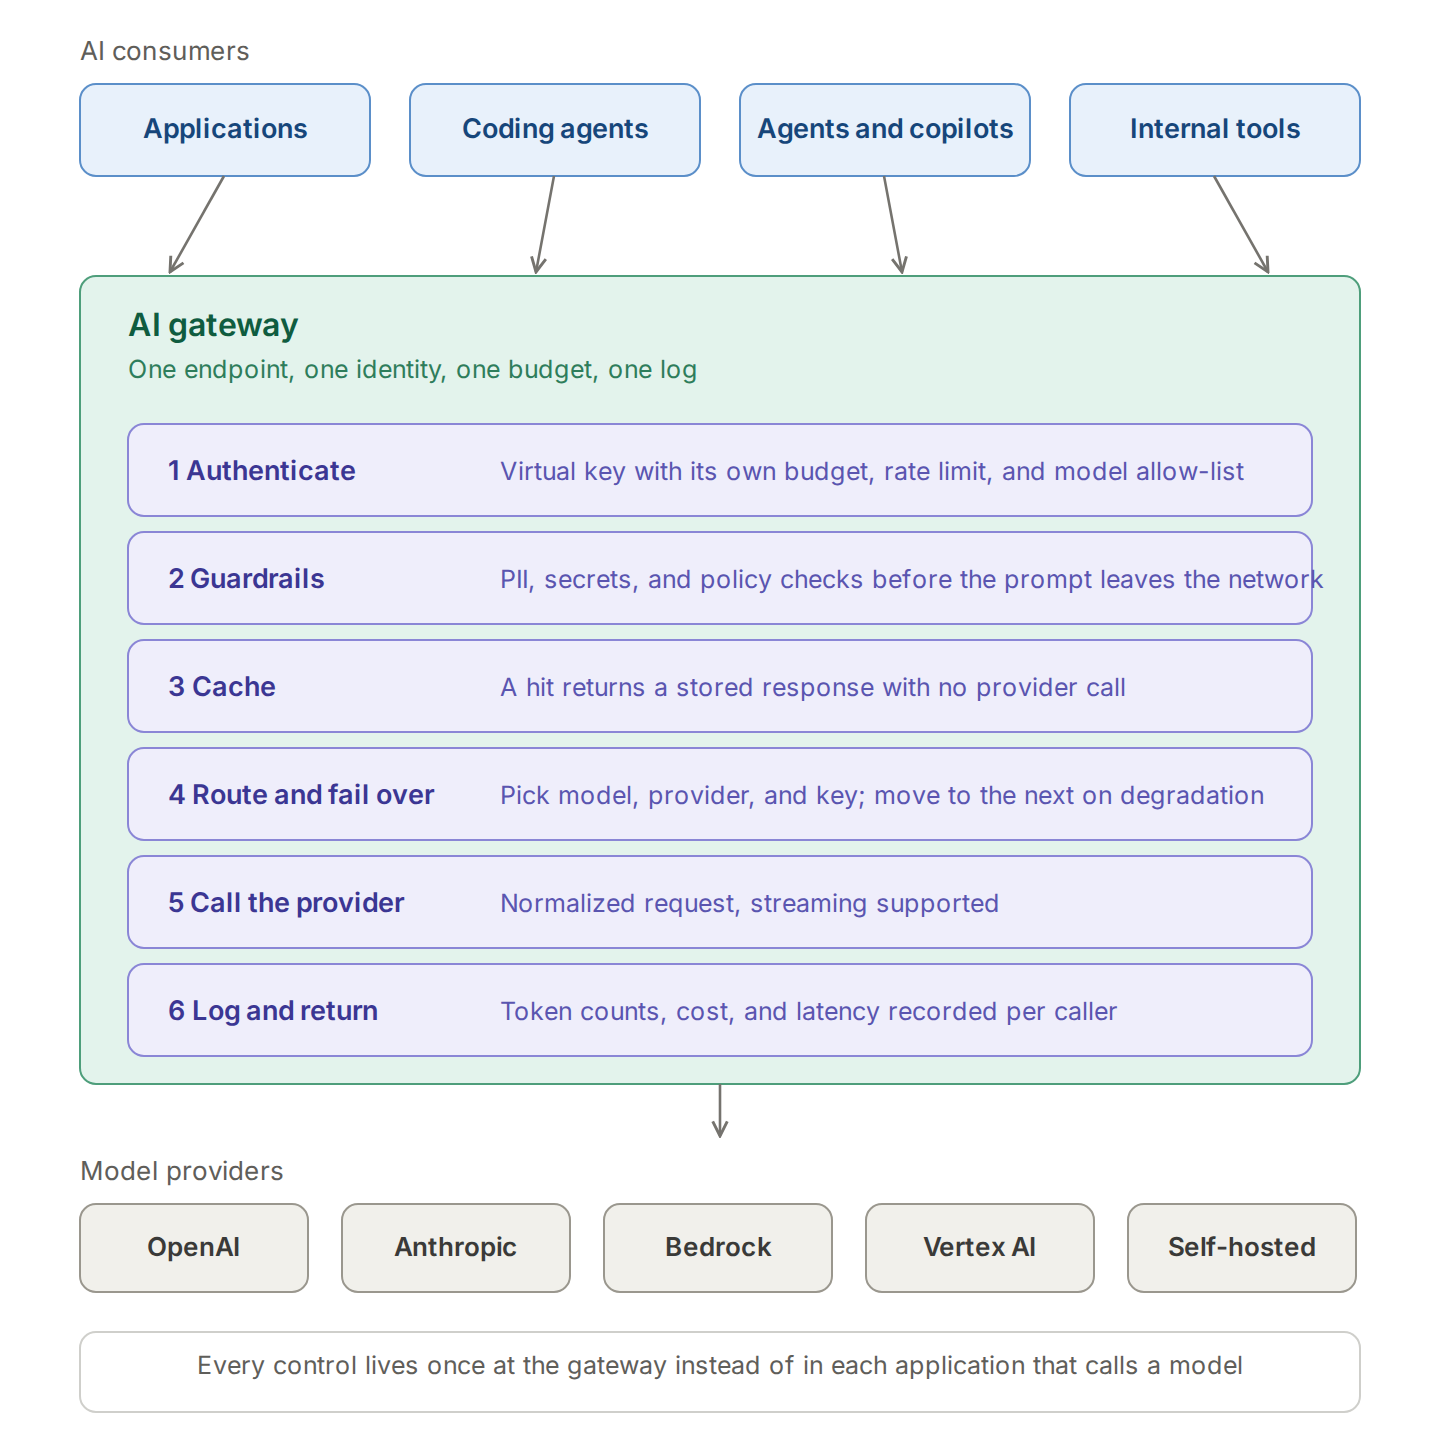
The consumers on the other side of the gateway are no longer only application code. Four kinds of AI traffic now pass through the same layer:
- Applications and services calling models for classification, extraction, summarization, or chat features.
- Coding agents such as Claude Code, Codex CLI, Cursor, and OpenCode, which make many model calls per task and connect to tools, covered in the guide to choosing an AI gateway for Claude Code.
- Agents and copilots that call tools through the Model Context Protocol as well as models.
- Unsanctioned AI use, where individual teams sign up for provider accounts directly. Traffic that never reaches the gateway cannot be budgeted, logged, or filtered, which is why discovery and enforcement belong in the same layer.
How a request moves through an AI gateway
A single request passes through the gateway in six steps:
- The application or agent sends an OpenAI-compatible request to the gateway endpoint instead of a provider SDK.
- The gateway authenticates the caller, usually with a virtual key that carries its own budget, rate limit, and model allow-list.
- Guardrails inspect the prompt for PII, secrets, and policy violations before it leaves the network.
- The cache is checked; a hit returns a stored response without a provider call.
- Routing picks the model, provider, and key, and failover moves to the next option if the primary is degraded.
- The response is scanned, logged with token counts and cost, and returned in a normalized format.
How an AI Gateway Differs from a Traditional API Gateway
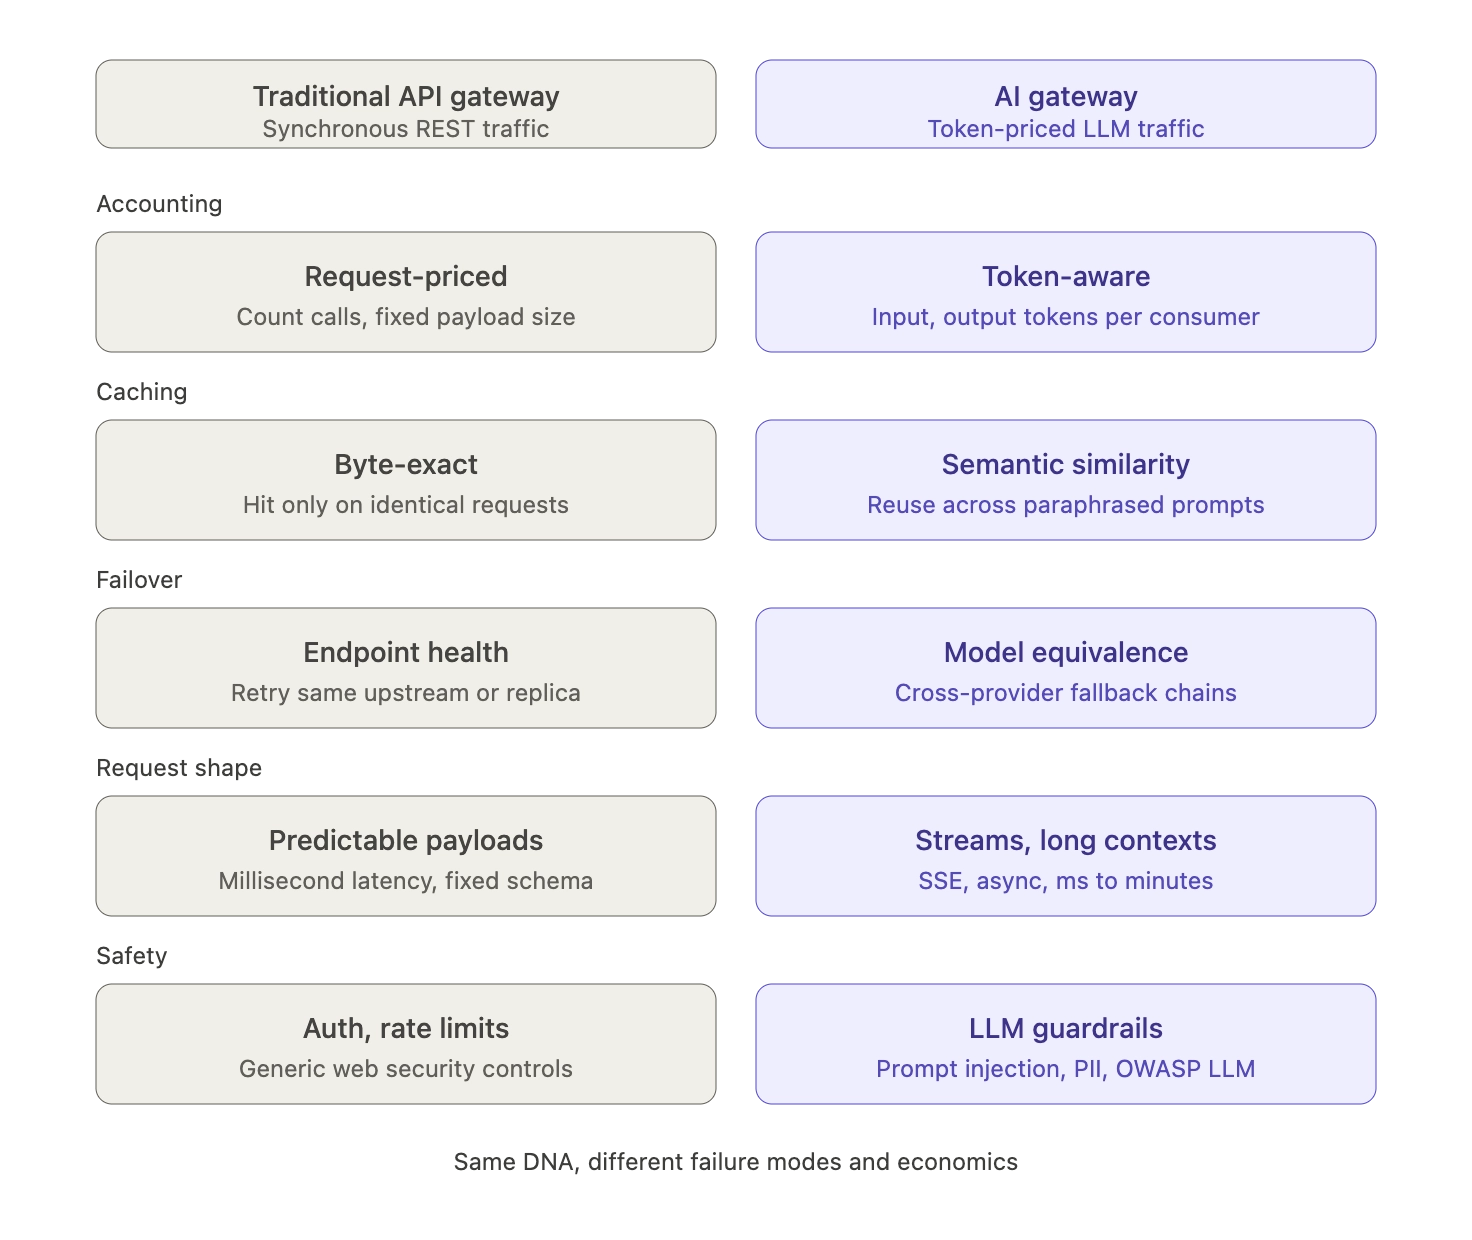
Traditional API gateways such as Kong, NGINX, or Apigee were designed for synchronous, low-latency HTTP traffic with predictable payloads. They handle authentication, routing, rate limiting, and basic observability for RESTful APIs.
An AI gateway shares some of that DNA but solves a different class of problems. LLM traffic is token-priced rather than request-priced, latencies range from milliseconds to minutes, payloads include streaming responses and large context windows, and the failure modes are unique to generative AI (hallucinations, prompt injection, sensitive data leakage, runaway token consumption).
Key differences include:
- Token-aware accounting: AI gateways track input and output tokens per request, per model, per consumer, enabling cost attribution that a traditional gateway cannot provide.
- Semantic caching: Instead of byte-exact response caching, AI gateways cache based on semantic similarity, recognizing that "What is AI?" and "Explain artificial intelligence" can reuse the same response.
- Multi-provider failover: Failover decisions consider model equivalence, not just endpoint health. When OpenAI is degraded, the gateway can fail over to Anthropic Claude or AWS Bedrock for the same logical task.
- Streaming and long-running requests: AI gateways handle SSE streams, partial responses, and asynchronous inference workflows natively.
- Content safety and policy enforcement: AI gateways apply guardrails, PII redaction, and prompt-injection defenses that are specific to LLM threat models. The OWASP Top 10 for LLM Applications identifies prompt injection, sensitive information disclosure, and unbounded consumption as top risks, all of which are naturally addressed at the gateway layer.
| Dimension | Traditional API gateway | AI gateway |
|---|---|---|
| Traffic profile | Synchronous REST, predictable payloads | LLM calls, streaming responses, large context windows |
| Pricing model handled | Per request | Per token, tracked by input/output, model, and consumer |
| Caching | Byte-exact response caching | Semantic caching by embedding similarity |
| Failover logic | Endpoint health | Model equivalence across providers |
| Security focus | Auth, rate limiting | Prompt injection, PII redaction, content safety (OWASP LLM Top 10) |
| Cost attribution | Request counts | Token-level, per team and per consumer |
The comparison that confuses teams more often is between the AI-specific gateways themselves.
AI Gateway vs LLM Gateway vs MCP Gateway
An LLM gateway routes model traffic, an MCP gateway routes agent tool calls, and an AI gateway is the layer that covers both plus the governance that applies to all AI traffic. In practice the three names overlap heavily, and several products, Bifrost included, perform all three roles from one binary.
| LLM gateway | MCP gateway | AI gateway | |
|---|---|---|---|
| Traffic it handles | Model requests: chat, embeddings, images, audio | Tool discovery and tool calls over MCP | Both, plus any other AI traffic |
| Primary controls | Routing, failover, caching, token budgets | Tool allow-lists, per-user credentials, execution approval | Every control above, applied to one identity and one budget |
| Typical consumers | Applications and services | Agents, copilots, coding agents | All of them |
| What it logs | Model calls with token counts | Tool calls with server and outcome | Both, in one trail |
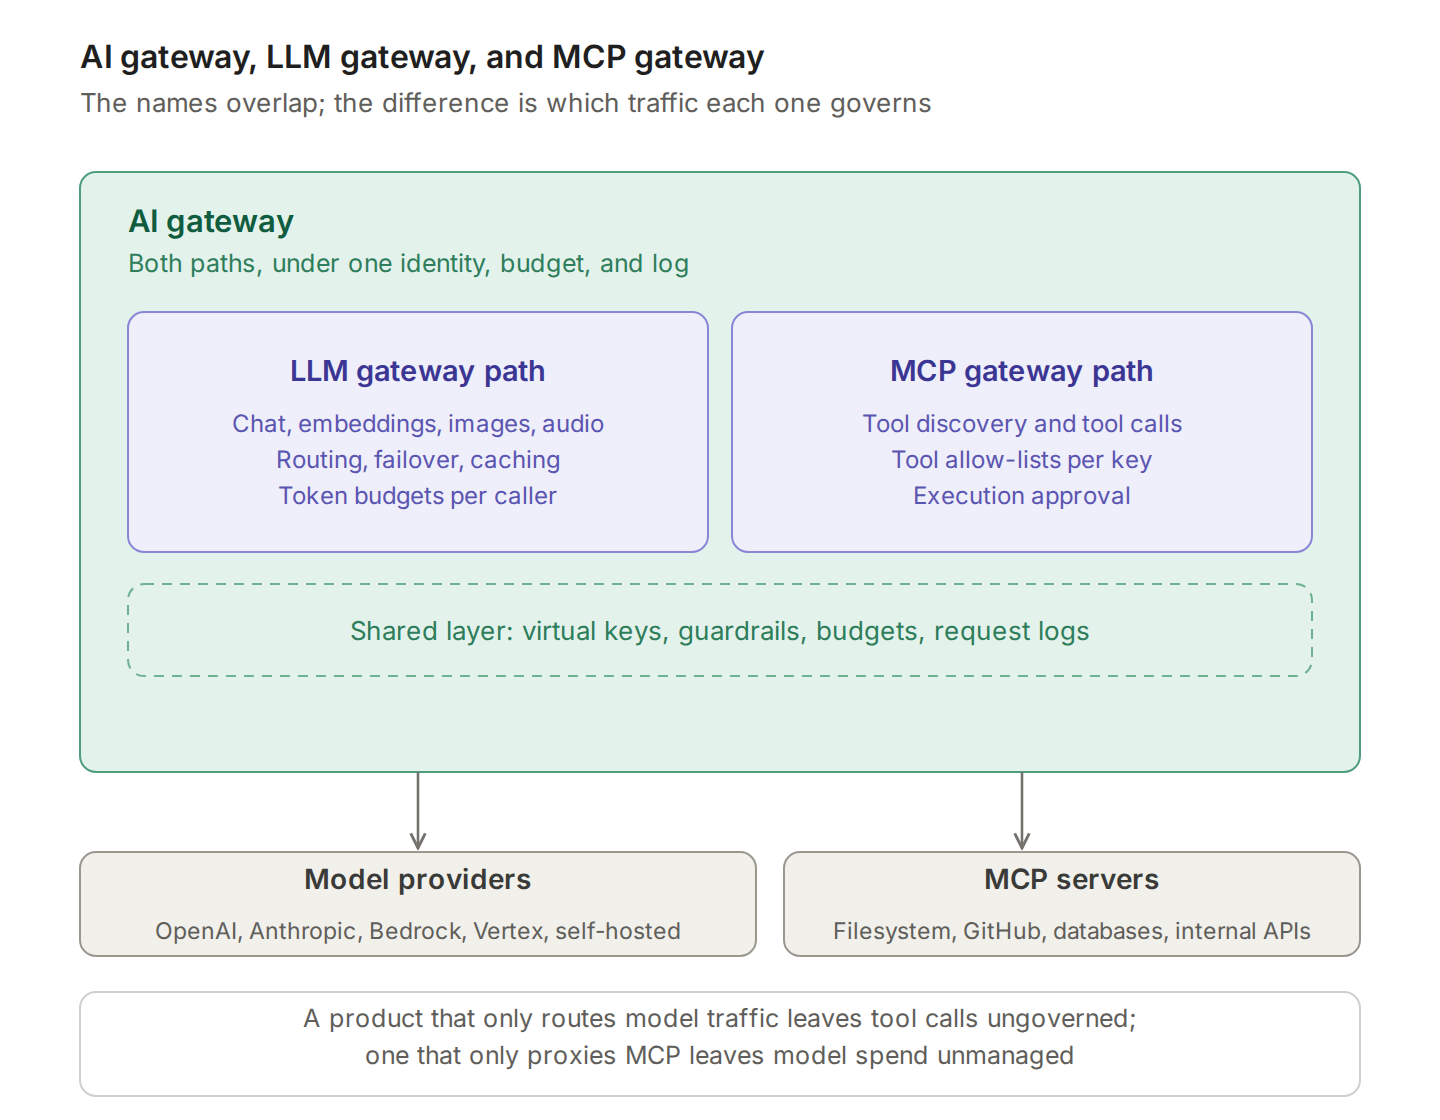
The distinction matters when buying: a product that only routes model traffic leaves agent tool calls ungoverned, and a product that only proxies MCP leaves model spend unmanaged. Deeper treatments are in what an LLM gateway is and what an MCP gateway is.
Why AI Gateways Matter for Enterprise AI Teams
The business case for an AI gateway becomes clear once an organization has more than one AI feature, more than one provider, or more than one team consuming LLMs.
Cost control and visibility
LLM costs are unpredictable because token usage varies per query. A single complex prompt can consume 10x more tokens than expected, and without centralized monitoring, spend can spiral. Gartner forecast in March 2026 that inference on a one-trillion-parameter model will cost providers over 90% less in 2030 than in 2025, but until that arrives, every team needs hierarchical budgets, rate limits, and real-time spend dashboards. Bifrost's virtual keys and budget management deliver these controls at the gateway layer, with hierarchical cost caps at the virtual key, team, and customer levels.
The gateway-level options for cost control are compared in enterprise AI gateways for controlling AI costs, and semantic caching removes the cost of repeated requests entirely.
Reliability and uptime
Provider outages are not hypothetical. OpenAI, Anthropic, and other vendors have all had multi-hour incidents that knock dependent applications offline. An AI gateway with automatic failover across providers keeps applications running by routing to a backup model whenever the primary degrades, with no application-level changes required. The same layer absorbs provider rate limits and outages and spreads traffic with load balancing.
Governance and compliance
Auditability is non-negotiable in regulated industries. Every LLM request that touches customer data must be logged, attributable, and reviewable. Bifrost's governance layer provides signed audit logs of administrative activity for SOC 2, GDPR, HIPAA, and ISO 27001 requirements, alongside request logs for every model and tool call.
Enterprise deployments add RBAC, SSO through Okta and Microsoft Entra ID, and secret management with AWS Secrets Manager, GCP Secret Manager, or HashiCorp Vault, so plaintext API keys never sit in the gateway database.
How teams apply these controls in practice is covered in governing LLM usage in the enterprise.
Multi-provider flexibility
Hard-coding to a single provider creates lock-in. An AI gateway turns provider choice into a configuration decision instead of a code rewrite. Teams can route reasoning-heavy tasks to one model, high-volume low-complexity tasks to another, and switch models in production without redeploying code, the pattern compared in AI gateways with multi-LLM support. It also removes single-vendor dependency, which is why OpenRouter alternatives and self-hosted options get evaluated together.
What the gateway solves, by role
| Role | The problem they bring to the gateway | What the gateway gives them |
|---|---|---|
| Platform engineering | Every team integrates providers separately | One endpoint, one SDK change, shared failover and caching |
| CTO or head of engineering | Agents and coding tools multiply model calls | Per-team budgets, model allow-lists, usage visibility |
| CISO or security | Prompts and outputs carry sensitive data | Guardrails, PII redaction, secrets detection, access control |
| Finance or FinOps | AI spend arrives as one provider invoice | Token-level attribution per team, customer, and feature |
| Compliance | Regulators ask who called which model with what data | Request logs per call and signed audit events for changes |
Core Components of an AI Gateway Architecture
A production-grade AI gateway typically provides the following capabilities:
- Unified API: A single OpenAI-compatible interface that abstracts every supported provider. Bifrost offers a drop-in SDK replacement where switching from a direct OpenAI integration to a gateway-mediated one requires changing only the base URL.
- Provider routing: Rules-based and weighted routing that directs requests to specific models, providers, or API keys based on cost, latency, or capability requirements.
- Failover and load balancing: Automatic detection of provider degradation, with intelligent fallback chains across providers and keys.
- Caching: A direct cache replays an identical earlier request without a provider call, and semantic caching matches requests by embedding similarity, so "What is AI?" and "Explain artificial intelligence" can share a response. Both reduce latency and cost.
- Governance primitives: Virtual keys, budgets, rate limits, and access controls scoped to consumers, teams, and projects.
- Observability: Real-time request logging, OpenTelemetry-compatible distributed tracing, and Prometheus metrics for production monitoring, the criteria compared in enterprise AI gateways for LLM observability. Gartner predicts that LLM observability investments will reach 50% of GenAI deployments by 2028, up from 15% today.
- Guardrails: Content safety, PII redaction, secrets detection, and policy enforcement applied to every request and response before they reach the application or the provider, as compared in AI gateway security options.
The MCP Gateway: AI Gateways Extended for Agents
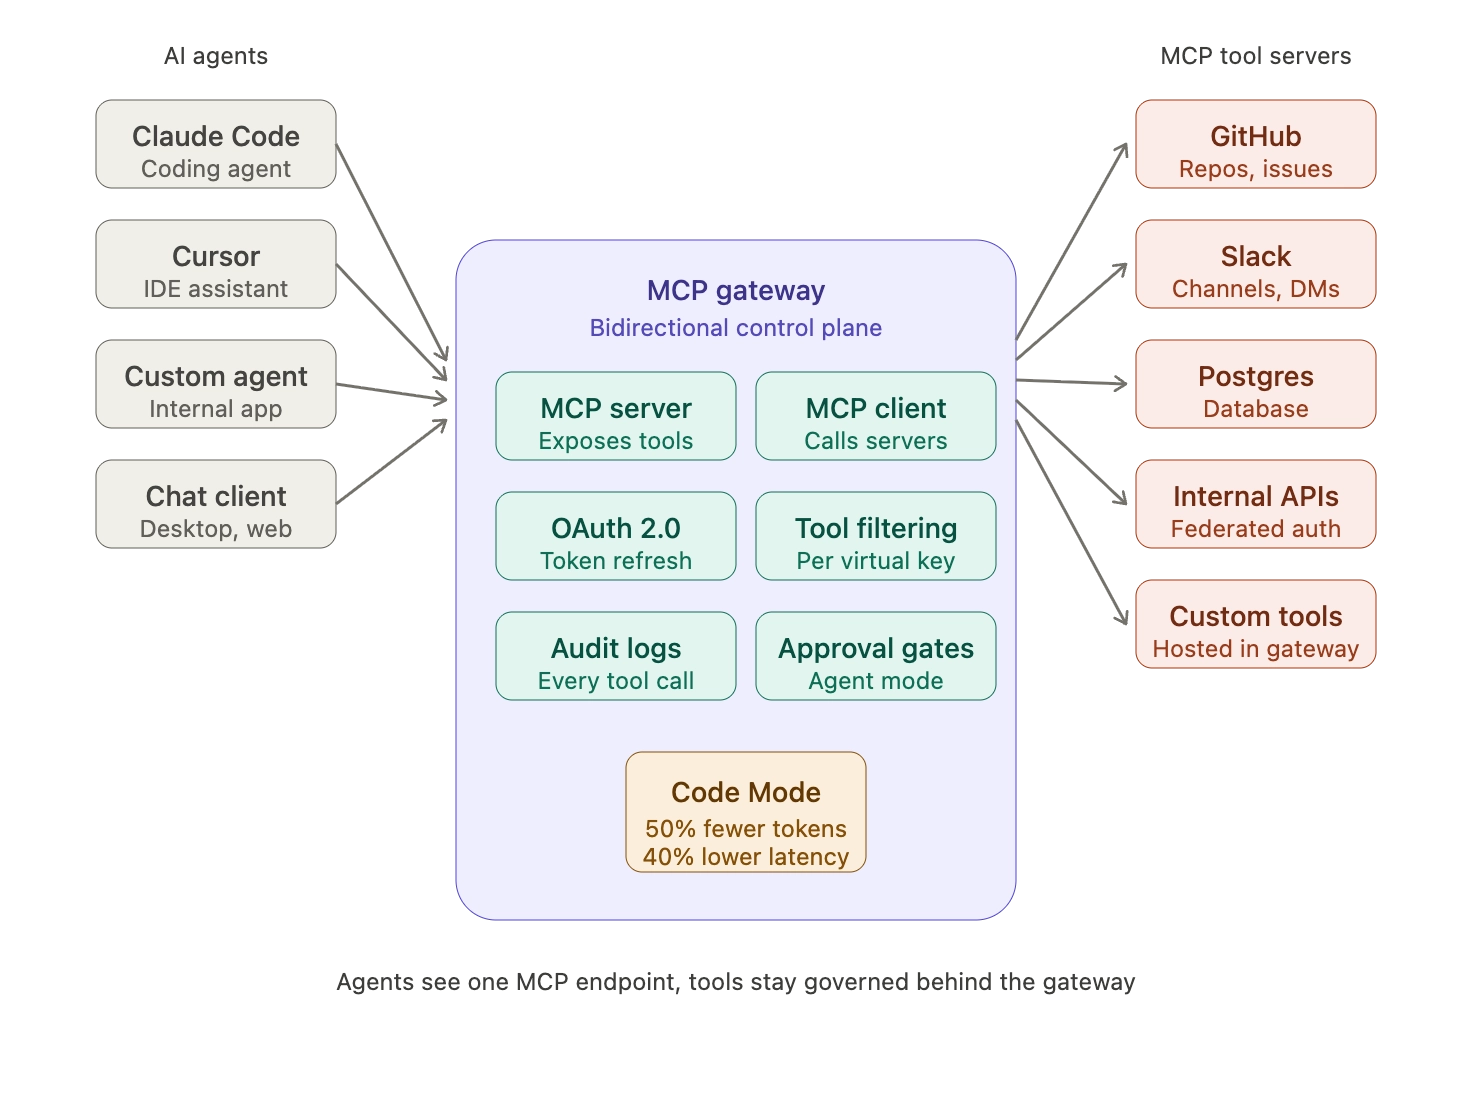
The rise of AI agents has expanded the gateway's role beyond LLM routing into tool orchestration. Anthropic introduced the Model Context Protocol (MCP) in November 2024 as an open standard for connecting AI agents to external data sources and tools. MCP has since been adopted as the de facto industry standard for agent-tool integration, with thousands of MCP servers in the ecosystem.
An MCP gateway centralizes all MCP server connections, applies governance and access controls to tool calls, and prevents the security blind spots that emerge when individual applications embed MCP clients directly. Bifrost's MCP gateway acts as both an MCP client and MCP server, with OAuth 2.0 authentication, per-virtual-key tool filtering, and Code Mode (where the AI writes Python to orchestrate multiple tools, reducing token usage by 50% and latency by 40%). This addresses the same problem Anthropic's own engineering team has documented: as agents connect to more tools, loading all tool definitions upfront consumes excessive context and increases costs.
For deep dives on MCP gateway architecture, access control, and cost governance, see the Bifrost MCP Gateway technical guide.
Key Considerations When Choosing an AI Gateway
Evaluating an AI gateway should be a structured exercise, not a vendor pitch comparison. The most important dimensions are:
- Performance overhead: Gateways sit in the hot path of every request. Latency added by the gateway compounds at scale. Bifrost adds only 11µs of overhead at 5,000 RPS, validated in independent performance benchmarks.
- Deployment model: Self-hosted, cloud-managed, or hybrid. Regulated industries often require in-VPC or air-gapped deployments with no external dependencies.
- Provider breadth: How many LLM providers are natively supported, and how quickly are new providers added when they launch.
- Governance depth: Virtual keys, RBAC, SSO, audit logs, secrets management integration, and budget hierarchies.
- MCP and agent readiness: Whether the gateway supports MCP as both client and server, with tool filtering and OAuth authentication.
- Observability integrations: Native support for Prometheus, OpenTelemetry, Datadog, New Relic, and other monitoring stacks.
- Open source vs. proprietary: Open-source gateways such as Bifrost (Apache 2.0) allow transparent inspection, community contribution, and freedom from vendor lock-in.
For a complete capability matrix across deployment, governance, and performance dimensions, the LLM Gateway Buyer's Guide provides a structured framework for evaluation.
Getting Started with an AI Gateway
The fastest way to evaluate an AI gateway is to deploy one and route real traffic through it. Bifrost is open source and requires no configuration to start. Install with a single command:
npx -y @maximhq/bifrost
Or run via Docker:
docker run -p 8080:8080 -v $(pwd)/data:/app/data maximhq/bifrost
The built-in web UI handles provider configuration, virtual key creation, and routing rules visually. Existing applications can migrate by changing only the base URL in the OpenAI, Anthropic, or LiteLLM SDK to point at the Bifrost endpoint.
For production deployments, the Bifrost Kubernetes deployment guide covers clustering, high availability, and scaling patterns. Enterprise teams running mission-critical AI workloads can explore Bifrost's clustering, adaptive load balancing, and in-VPC deployment options through a direct conversation: book a demo with the Bifrost team to see how a production-grade AI gateway can simplify your AI infrastructure.
Frequently Asked Questions
What is the purpose of an AI gateway?
An AI gateway centralizes control over all traffic between applications and AI model providers. Its purpose is to make the AI stack operable like any other infrastructure: one interface for many providers, enforced budgets and access policies, automatic failover, semantic caching, and audit-ready observability. Without it, these controls have to be rebuilt in every application that calls a model.
What are the key differences between an API gateway and an AI gateway?
A traditional API gateway manages synchronous REST traffic priced per request. An AI gateway handles token-priced LLM traffic with streaming responses and large context windows, caches on semantic similarity rather than exact matches, fails over on model equivalence across providers, and defends against LLM-specific risks such as prompt injection and sensitive-data leakage.
What are the most popular AI gateways?
Popularity varies by audience. Among open-source options, Bifrost has seen fast adoption for enterprise and high-throughput workloads because it combines 23+ providers, 11 microseconds of overhead at 5,000 RPS, native MCP support as both client and server, and self-hosting under Apache 2.0. Managed and cloud-native gateways are common where zero operational overhead is the priority.
Can you provide some examples of AI gateway capabilities?
Core capabilities include a unified OpenAI-compatible API across providers, rules-based and weighted routing, automatic failover and load balancing, semantic caching, virtual keys with hierarchical budgets and rate limits, OpenTelemetry and Prometheus observability, and guardrails for content safety and PII redaction. Bifrost provides all of these plus an MCP gateway for governing agent tool calls.
Does an AI gateway support AI agents and MCP?
Yes. As agents connect to more tools, an AI gateway centralizes MCP server connections and applies access control to every tool call. Bifrost acts as both an MCP client and server, with OAuth 2.0 authentication, per-virtual-key tool filtering, and Code Mode, where the model writes Python to orchestrate tools instead of loading every tool definition into context.
Does an AI gateway add latency to requests?
A well-engineered gateway adds negligible latency. Bifrost adds roughly 11 microseconds of overhead per request at 5,000 RPS, validated in independent benchmarks, so the gateway hop is not a meaningful contributor to end-to-end response time. The failover and semantic caching it provides usually reduce tail latency more than the gateway adds.